AI Operational Platform for a Professional Services Firm

A Modular AI Operational Platform for a Multi-Entity Professional Services Firm

How creating a company-wide AI operational layer with several AI agents and governance by design enabled a German professional services group to accelerate request processing by 72%, cut fee proposal preparation time by 65%, and free each employee from 6 hours of repetitive administrative work weekly.

Business challenge

Professional services firms in law, finance, and consulting run on trust, context, and responsiveness. In legal, tax, and accounting, the difference between a good client experience and a missed opportunity often comes down to how quickly the right person understands the request, connects it to the right matter, and moves it forward.

But as such companies grow beyond a single practice, the operating model often becomes harder to control. What works for a compact law firm starts to strain when several business units share clients, brand equity, and expertise, but not the same workflows, systems, or view of client history.

Our client, a Germany-based professional services group with assurance, tax, legal, and management consulting business units, had reached that inflection point. Around 100 full-time professionals and part-time consultants across the country supported a shared client base, while customer tracking and project management remained fragmented across business units.

The friction showed up in several places at once:

  • Email as the de facto operating system. Client requests, project updates, document exchanges, internal coordination, and cross-unit referrals all originated and evolved inside email conversations. What they lacked was structured intake, routing logic, and a quick, unified way to track what came in, who owned it, or what happened next.
  • Manual operations. Even routine requests required attention from senior lawyers, tax advisors, auditors, and consultants, pulling highly qualified professionals into administrative work. Moreover, with most of the proposal fee preparation done by hand, the client’s customers waited for days for what competitors with proper automation delivered in hours.
  • Informal and under-structured workflows across business entities. Cross-unit coordination happened ad hoc rather than through structured processes. A legal client asking a tax-related question would trigger a phone call or a forwarded email, as there was no controlled workflow.
  • Low visibility into projects and matters. Each team maintained its own matter records in simplified Excel sheets and DMS templates, leaving the company without a unified view of active matters, ownership, and status.
  • AI adoption lagging behind. While aware that incorporating artificial intelligence into their daily operations was no longer a nice-to-have, the client still lacked a cohesive plan for implementing it.

With these problems snowballing and no in-house expertise to tackle them, the client turned to Instinctools’ AI Center of Excellence.

Solution

From the beginning, the project was not treated as a chatbot implementation, where another isolated AI tool sits on top of already fragmented workflows. The client needed a controlled AI operating layer that could connect inboxes, documents, matter data, internal systems, and human decision-making into one governed workflow.

For law firms, confidential AI solutions with data privacy and compliance built in aren’t optional, as lawyers, auditors, tax advisors, and consultants work with sensitive client data and carry personal responsibility for the advice they provide. AI could help reduce repetitive operational work, but only if every output remained traceable and reviewable.

Considering that context, Instinctools designed the solution around three principles:

  • Sensitive client data must remain under the client’s control
  • AI outputs must be auditable and explainable enough for professional review
  • Every AI-assisted workflow must keep a qualified human in the loop

The platform was built to support four core capabilities from the start:

  • Email intake and matter management 
  • Employee support
  • Quoting support
  • Advisory document analysis
  1. Choosing a platform approach over one-off AI tools

The client wanted to move quickly, but they also needed the solution to scale across several business units. Building one AI tool at a time would have solved individual problems, but it would also have recreated the same fragmentation the company was trying to overcome.

Instinctools proposed a platform-based approach powered by GENiE, our proprietary agentic AI framework. The idea was to build the foundation once (integrations, context layer, agent orchestration, governance, auditability, and data access) and then reuse it across every subsequent AI module.

What exactly did this approach bring to the table?

  • Centralized AI governance inheritance. With governance, auditability, and compliance controls embedded at the platform level, every new AI solution inherited them automatically.
  • Data platform with adapters. Pre-built connectors unified the company’s DMS, accounting platform, time-tracking tool, and Microsoft 365 services into a single queryable layer.
  • Cross-agent context synchronization. It is what makes agentic AI for law firms workable in practice: all AI agents operate within a shared context that connects customers, matters, relationships, and services. Besides eliminating duplicate data entry, this approach enables richer operational intelligence over time.
  1. Starting with what hurt most: email intake and matter management

The first of the AI agents for the law firm’s operational layer our team developed was the email intake and matter management agent.

Much of the company’s work began in Microsoft 365 inboxes: new client requests, follow-ups, internal referrals, document exchanges, administrative questions, and updates on existing matters. Our team connected the platform to the client’s mailboxes and built a processing pipeline that frees lawyers, tax advisors, auditors, and consultants from repetitive triage work.

When an email comes in, the agent:

  • Classifies the intent (new engagement, follow-up, internal referral, or administrative request)
  • Identifies whether the sender is an existing client or a new prospect
  • Determines which business unit should handle the request
  • Checks whether the email relates to an active matter or suggests creating a new matter record when no match is found
  • Surfaces deadlines, obligations, and required next steps for professional review

The agent processes emails in German and English.

Getting the classification right across four business units with different vocabularies was one of the project’s tough puzzles. Tax advisors, lawyers, consultants, and assurance specialists may describe similar work differently or use the same term to mean different things. To address this, our business analyst collaborated with domain experts from each unit to map service categories, routing rules, and matter hierarchies. Where the business units adhere to common logic, the system uses shared classifications. Where they diverge, it maintains unit-specific configurations.

The agent was first tested with a champion group of 10 users. Initial classification accuracy reached around 74%. Through few-shot tuning with real company emails and structured feedback from the early adopters, we raised the accuracy to 87%, exceeding the client’s initial 85% target.

After validation, the email intake and matter management agent was rolled out across all business units. This gave the client a structured intake mechanism and created the foundation for a big-picture dashboard showing active matters, task ownership, and engagement status across the entire company. That way, the AI platform brings multiple practice areas into a single workspace, saving managing partners from calling around or digging through email threads to find out what’s happening.

  1. Broadening AI usage across the company

After the email intake and matter management agent proved stable in production, we began extending the AI systems across the professional services firm’s law, consulting, and finance operations.

Employee assistant chatbot in 2 weeks

Before rolling out AI agents for higher-stakes operations like quoting or advising, we wanted the company’s staff to get comfortable with AI-assisted workflows in a low-risk setting.

We designed and deployed an assistant chatbot that gave employees a controlled environment to interact with AI in everyday scenarios. It operates in German and English, matching the company’s working languages, and answers routine internal questions about leave policies, expense procedures, onboarding steps, IT access, and more, drawing from the company’s HR documentation and operational FAQs. When it can’t answer with sufficient confidence, it routes the query to the right person with context already attached, so nobody has to re-explain the question.

A dashboard shows a chat with a knowledge assistant about travel and business expenses. The left menu lists Dashboard, Names, Requests, Messages, and Knowledge Assistant. The right panel highlights “Travel and Expenses” with statuses: Awaiting response and Answered.

Beyond building trust in AI across the workforce, the chatbot absorbed the stream of repetitive questions that used to land on managers and office admins, freeing each for up to 6 hours of meaningful work a week.

Quoting agent in 3 weeks

Next, Instinctools’ team built an enterprise AI agent for the law firm’s quoting process, turning manual fee proposal preparation into a structured, step-by-step workflow. When a new client request is confirmed through the email intake agent, the quoting agent takes over:

  • Reading the client request and mapping it to the company’s services (tax structuring, legal review, due diligence, etc.)
  • Finding the right people for the job based on skills and experience
  • Checking who’s free through the client’s time-tracking system
  • Drafting a fee proposal based on the company’s rate cards for manager review

What used to be an email back-and-forth across partners, associates, and office admins now runs through a single structured workflow, with AI laying the groundwork and the professionals making the final call.

Advisory agent in 4 weeks

Due diligence packages, regulatory filings, and contract portfolios are the kind of high-stakes documents where volume makes manual review unacceptably slow. To ease the daily burden of the client’s advisory and assurance teams, we built an agent that took on the heavy lifting. It runs within the AI platform built specifically for law firm operations:
  • Ingesting PDF, DOCX, and XLSX documents up to 200 pages long
  • Producing summaries at the level of detail the professional needs, from a quick overview to a section-by-section breakdown
  • Cross-referencing findings across multiple documents to surface non-obvious patterns, contradictions, and gaps

Every AI-generated finding links back to the exact source document, page, and section, so advisory and assurance staff can verify the evidence in seconds.

On the data handling side, the agent classifies documents by sensitivity level:

  • Publicly available materials like regulatory filings, published financial statements, and industry reports are processed through the cloud inference layer under the existing no-retention agreement.
  • Highly sensitive documents, such as materials covered by attorney-client privilege or pre-announcement M&A data, are processed entirely on-premises and never leave the client’s servers.

Setting up the governance framework and platform foundation took six weeks. The multi-agent system with the assistant chatbot, email intake, quoting, and advisory agents was ready in 14 weeks, bringing the entire delivery timeline down to five months, well ahead of the client’s original 8-10-month estimate.

Banking on GENiE showed in the numbers
  1. Cost-effective governance by design

For the platform to operate safely across all business units, we set up a robust AI governance framework from the get-go. 

  • All application servers, databases, and data pipelines run on the company’s own infrastructure. Customer data, matter records, and document embeddings never leave the premises.
  • Only anonymized, tokenized fragments are sent to Azure OpenAI EU West for inference, under an enterprise agreement that guarantees no retention or training on the company’s data.
  • The framework defines how AI document review works for law firms operating under strict confidentiality: AI outputs are treated as working drafts until reviewed and approved by a qualified professional. This keeps human oversight built into the workflow and reflects professional liability requirements under German laws such as BRAO, StBerG, and WPO, as well as the EU AI Act’s human-oversight expectations.
  • Every action any AI component takes is captured in a mandatory audit trail with a 12-month retention period: what decision was suggested, how confident the model was, and whether a professional approved or overrode it. This data can be pulled at any time in a format ready for regulators and auditors.

Here’s how NDAs, engagement letters, and service agreements are handled within the AI operational layer.

Flowchart with two faded boxes on top labeled “Matter record” and “Company templates.” The center green box says, “AI generates first draft. Flags missing or inconsistent fields.” Below is a purple box, “Professional review. Tracked-changes interface.”.

For a company that bills by the hour and watches margins closely, AI spend transparency was a practical concern from day one. To keep inference costs predictable and deliver robust governance without breaking the bank, our team built a cost-tiered AI gateway that routes routine classification to small, lightweight models and assigns complex analysis and document generation to larger models.

The client’s priority wasn’t “governance at any cost”

Before

  • Email inboxes as the company’s informal operating system led to transparency and coordination challenges
  • Manual customer intake, matter handling, and quoting wasted senior professionals’ billable time
  • Client history, matter context, and referral opportunities stayed fragmented across teams and individuals
  • No real-time visibility into active matters, ownership, workloads, and engagement status

After

  • An AI operational layer with strong governance unlocked transparency and seamless cross-unit coordination
  • AI agents took over administrative groundwork, freeing professionals for higher-value expert work
  • Shared operational context unified customer and matter knowledge across business units
  • Managing partners gained real-time visibility into workloads, matter ownership, active engagements, and cross-unit coordination

Business value

  • Real-time cross-unit visibility thanks to a company-wide AI operational layer
  • + 72% in request processing speed
  • – 65% in fee proposal preparation time
  • – 6 hours/week of repetitive administrative work per employee

Multiplier effect

The productivity loss this project addressed goes far beyond legal, tax, and finance. In any knowledge-intensive business, highly qualified people spend too much time on coordination work: routing requests, reconstructing context, chasing updates, preparing drafts, and pulling information from scattered systems.

An AI operational layer with governed multi-agent systems is a way of automating those tasks without sacrificing visibility or control. AI agents take on the groundwork, so your staff spends less time chasing information and more time on the work you hired them for. Companies can start with the biggest time sink and, then, expand gradually as each use case proves its value.

Overhead view of people working at a table with laptops, tablets, charts, and notebooks. A glowing “AI” graphic and digital icons are superimposed, symbolizing artificial intelligence and data analysis. Hands are busy typing or writing.

AI-Powered Knowledge Platform For a Wind Turbine Manufacturer

AI-Powered Knowledge Platform For a Wind Turbine Manufacturer

How developing a conversational AI knowledge platform with offline access and peer-to-peer expertise sharing enabled a European wind turbine manufacturer to turn post-sale field support into a product differentiator and reduce support queries by 37%.

Business challenge

When a turbine stops or triggers an alarm miles from the nearest office, the repair depends on how fast the technician on site can find the right answer. For field workers servicing wind turbines offshore and over sprawling onshore locations, that process is riddled with friction.

  • No single source of truth. Maintenance manuals, monitoring guides, technical bulletins, and troubleshooting references exist, but are scattered across multiple portals and PDF libraries with no unified entry point. A technician looking for a specific calibration procedure might find it in three clicks or thirty, depending on which system they open first and whether they guess the right keywords.
  • Documentation built for desks, used on turbines. The materials are authored for screen-and-keyboard reading, but real-life wind turbine servicing conditions look nothing like that. Technicians access documents on phones or tablets, often one-handed, in rain or wind. Dense PDF layouts with no mobile optimization turn a two-minute lookup into a scrolling exercise.
  • Peer knowledge without a peer network. When documentation falls short, experienced technicians fill the gap. But that expertise is shared through phone calls, ad hoc messages, or chance conversations rather than through a structured channel. Two technicians in the North Sea and Andalusia might independently solve the same fault, weeks apart, with no way to learn from each other.

Our client, a major European wind turbine manufacturer, saw these hurdles as a product opportunity. As their relationship with every buyer extends into years of customer support, an application that would consolidate the company’s product maintenance knowledge into a single, searchable hub could not only ease post-sale support overhead but become a selling point in its own right.

They approached Instinctools with a vision for a companion app built around conversational AI: a tool, offered alongside the turbines themselves, giving field technicians a way to describe a problem in plain language and get an actionable, source-verified answer on the spot, with clear traceability back to the original material.

Solution

Some opportunities can’t wait for paperwork. While the project was still in the proposal stage, Instinctools built a working prototype that gave the client an early view of the product vision in action. It allowed their team to test assumptions, gather internal feedback, and validate the concept before committing to a vendor, budget, or full-scale delivery plan.

  1. Crafting a clickable prototype at the pre-sales stage

The client’s original brief centered on a searchable knowledge base with a conversational AI interface. Field technicians would type a question in their native language, and the system would return a plain-language answer drawn from the manufacturer’s documentation, with a citation trail pointing back to the source. Multilingualism was essential as the client’s install base spans dozens of countries.

Our AI developers and UX/UI designers translated the brief into a clickable prototype covering the core user journey:

Every screen was designed with field conditions in mind, as a technician may be using the app with one hand on the device and the other on a railing, tool, or flashlight. So the interface had to be simple, readable, and usable without desk-bound assumptions.

Still, documentation alone, however well-organized, can’t cover every edge case. Sometimes the answer can come from another technician who has already wrestled with the same fault on the same turbine model, somewhere else. So we went the extra mile to give this tribal knowledge a place inside the app by including something the client hadn’t asked for: a peer-to-peer knowledge sharing layer where technicians register which equipment they service, find colleagues working with the same wind turbines, and exchange solutions to tricky operation and maintenance issues through in-app messaging. 

What started as Instinctools’ suggestion, by the end of the prototype review landed in the MVP scope, transforming a knowledge base app into a broader AI-assisted field support platform grounded in source documentation and strengthened by a technician network.

  1. Laying the technical foundation for full-scale development

With the prototype approved and the scope expanded, Instinctools moved into architectural planning. Several technical decisions shaped the project from the start:

  • Single-vendor cloud and AI setup. We hosted the platform on AWS, picking the eu-central-1 region in Frankfurt to keep data physically inside the EU. AWS Bedrock handles the AI layer, providing access to Anthropic’s Claude within the same compliance boundary as the rest of the infrastructure.
  • Search architecture. The accuracy of a conversational AI assistant is rooted in the quality of the retrieval layer feeding it. Instinctools chose pgvector to combine semantic search with automatic profile-based hard filters in a single query, so when a technician asks about pitch system calibration, the results are already scoped to a particular turbine model. For a knowledge base sized at around 10,000 content chunks, this vector similarity search keeps the infrastructure lean without cutting corners on retrieval accuracy.
  • Zero-signal mode. Because technicians may work offshore or in low-connectivity environments, the app needed to stay useful even without a stable connection. We paired Workbox and IndexedDB to cache the app interface and store bookmarked documents locally within the app. Features that rely on live services, like AI search and community messaging, stay online-only.
  • Access control. For authentication, Instinctools went with Auth0, starting with invite-only registration during the MVP, so the client could control early access before opening to self-service registration. Password policies, account lockout, email verification, and recovery flows were handled through Auth0’s built-in identity-management capabilities.
  • Autotranslation layer. The client’s turbines operate across a multilingual EU market and beyond. The team chose DeepL’s API for on-demand translation, favoring it over alternatives for its stronger handling of technical content in European languages.
  1. Refining the prototype with field feedback

The prototype looked right on screen. To see if it’ll be of any help for end users, we shared it with a group of roughly 20 early testers the client gathered from its European customer base.

Several assumptions didn’t survive first contact with the field, but caught early, they became opportunities for improvement before full-scale development:

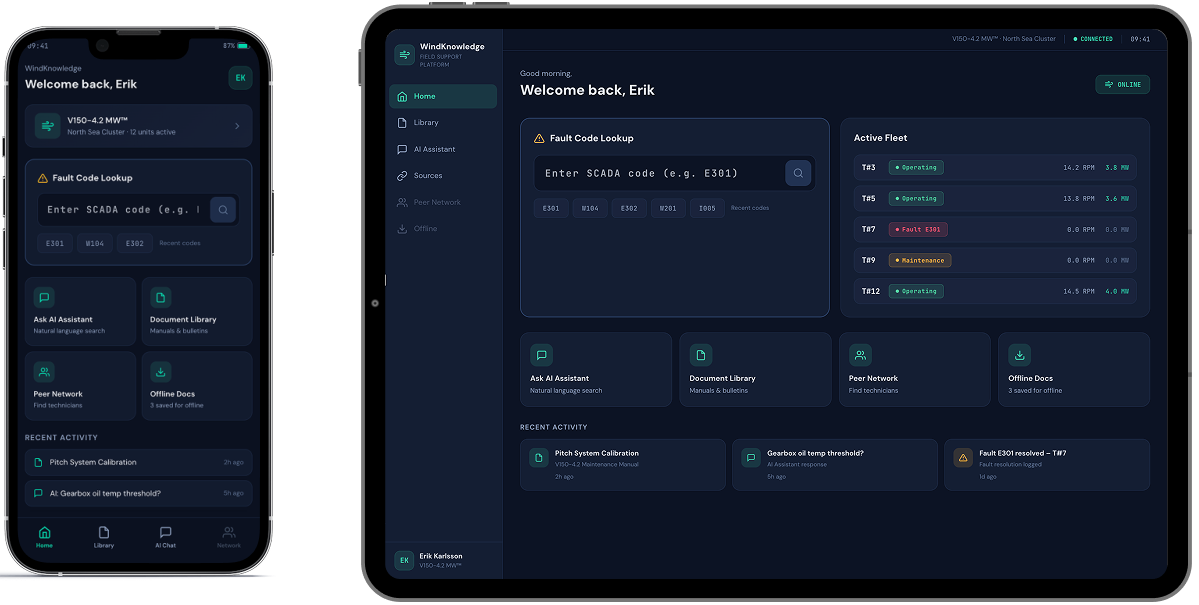
  • Fault-code workflow. The AI search handled natural language and fault codes equally well, but testers revealed that the vast majority of their queries start with a SCADA status code. This prompted us to update the home screen design by adding a dedicated fault-code entry field with auto-recognition, so the most common interaction pattern gets the shortest path.
  • Minimum taps to target. In the initial prototype, users had to open a document before saving it for offline access. Testers pointed out that before going offshore, they often need to save several guides at once. We redesigned the flow so documents could be saved directly from search results, without opening each one individually.
  • Expert knowledge sharing priorities. The prototype included a location-based map showing where other technicians were working, but users made it clear that proximity was not their top priority. They wanted to filter peers by turbine model and specialization first, and by location second. For a technician troubleshooting a specific gearbox issue, the right match was not the nearest colleague, but the one with relevant hands-on experience.
A smartphone and tablet display a dark-themed dashboard interface. Both screens show a welcome message, a fault code lookup bar, system status cards, and recent activity modules, with similar layout but resized for each device.

This feedback reshuffled the development backlog. We moved features like fault-code-driven search and single-tap document access from “could have” to “should have” status, ensuring the MVP reflected how technicians actually work, not just how the workflow looked in a prototype.

  1. Developing and rolling out an MVP

The MVP scope was deliberately focused: one turbine product line, one content library, and an upscale from 20 to 100 technicians. The goal was to prove the full end-to-end experience with a larger, controlled user group before replicating it across the client’s entire equipment catalog.

Here’s how the flow goes:

  1. During onboarding, the early adopters select the turbine models they service
  2. From that point on, the app personalizes search results, document recommendations, and community connections, so that a technician working with a specific model sees materials and peers’contacts relevant to that model, noise-free
  3. Every answer the AI assistant returns includes citations to the source document and section, so a technician can verify the guidance before acting on it.

This personalization engine sits on a knowledge base of hundreds of maintenance manuals, monitoring guides, technical bulletins, etc. Since it’s updated once a month at most, a real-time content synchronization would have added unnecessary complexity. A monthly content ingestion pipeline was enough to keep the knowledge base current without overengineering the backend.

Once rolled out to the full 100-technician group, the app saw steady organic adoption.

Before

  • Technical documentation scattered across multiple portals and PDF libraries
  • Only basic, document-level search capabilities
  • A multi-tap user journey to reach a single document, with no shortcut for the most common queries
  • Peer expertise shared informally through phone calls and personal contacts, if at all

After

  • A single AI-powered conversational app consolidating the wind turbines’ maintenance library
  • Advanced semantic search with optional hard filters across the whole knowledge base
  • One tap to target and fault-code auto-recognition field on the home screen
  • A structured peer network connecting technicians by turbine model, specialization, and relevant field experience

Business value

  • Post-sale support transformed into a product feature
  • – 37% requests escalated to the client’s customer support team
  • < 30 seconds from query to cited, source-verified answer
  • x2.5 faster troubleshooting of field incidents

Multiplier effect

The pattern behind this platform – consolidating scattered documentation into a conversational AI interface and pairing it with a peer network – is not limited to the energy sector. Any industry where field professionals work with dense technical libraries under time pressure faces similar friction: heavy machinery, medical devices, industrial automation, telecom infrastructure, and more. The infrastructure we built is modular to be useful for a different knowledge base and equipment catalog without being redesigned from scratch.

A person in a dark blue shirt holds a smartphone in one hand and types on a laptop with the other. Digital facial recognition icons and a checkmark appear, indicating successful facial authentication on the phone. The background is blurred.

Computer Vision Deepfake ID Detection

Computer Vision Deepfake ID Detection For a Dutch Digital Bank

How adding a custom computer vision layer to the existing SaaS ID verification platform empowered a Dutch digital bank to keep up with the evolving threat landscape and stop 30% more AI-generated identity fraud, while reducing false positives for real users by 60% and decreasing manual document review workload by 40%.

Business challenge

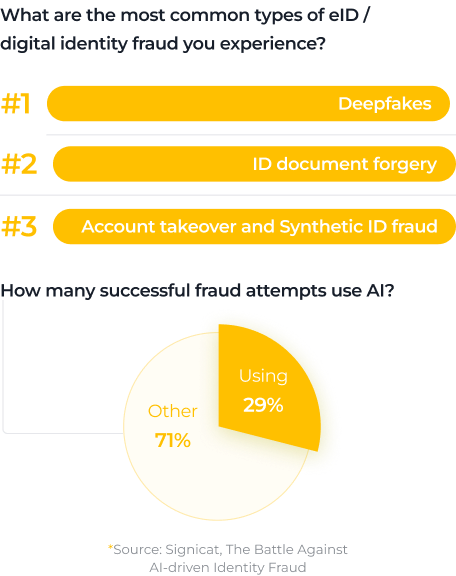
Bar chart listing common types of digital identity fraud: 1. Deepfakes, 2. ID document forgery, 3. Account takeover & synthetic ID fraud. Pie chart: 29% of successful fraud uses AI, 71% uses other methods. Source: Syntiant.
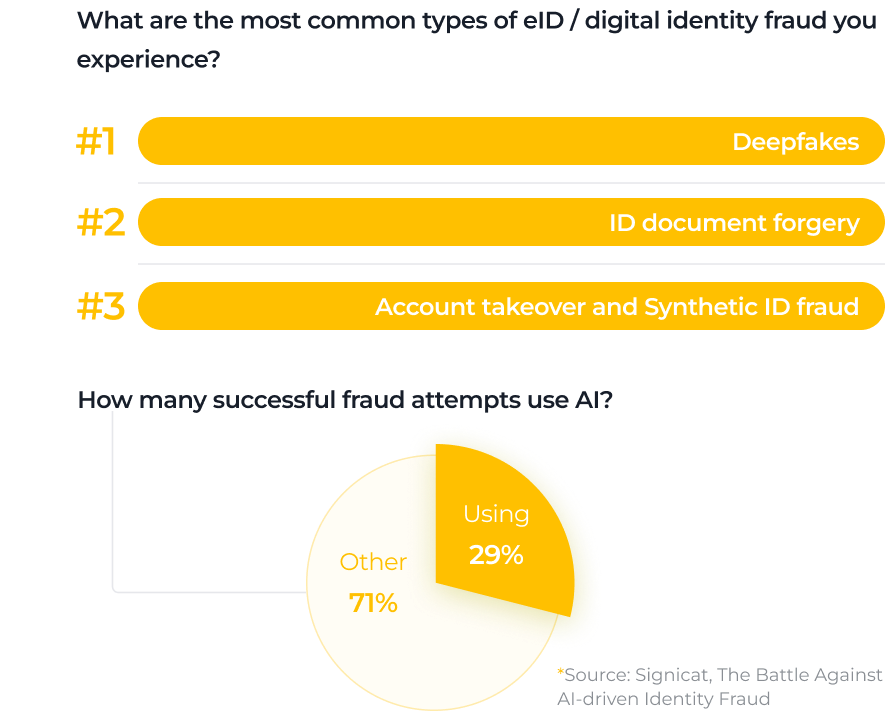
A graphic showing the top three eID/digital identity fraud types: #1 Deepfakes, #2 ID document forgery, #3 Account takeover and synthetic ID fraud. A pie chart shows 29% of successful fraud uses AI, while 71% is categorized as “Other.”.
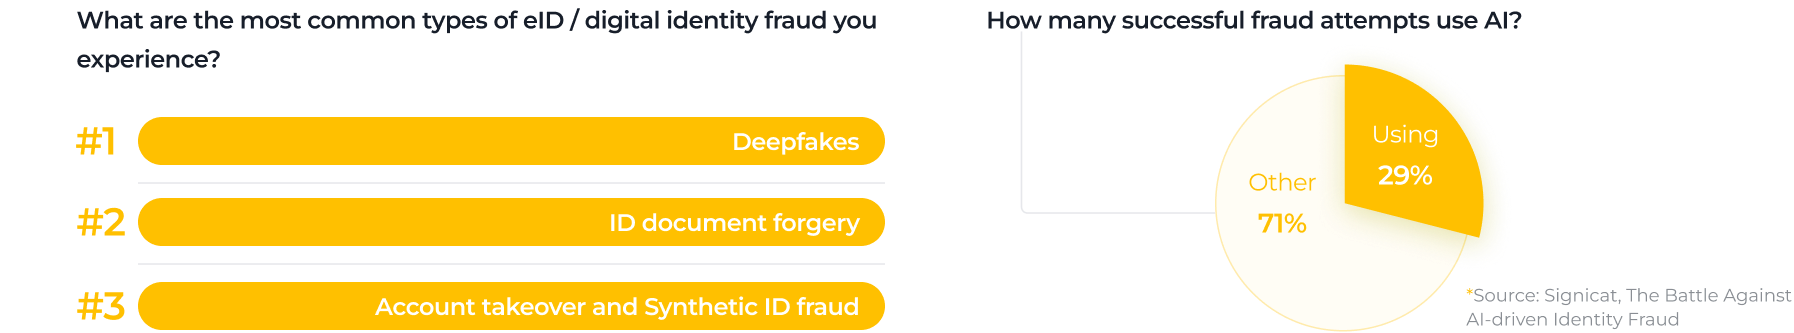
A graphic lists the top three eID/digital identity fraud types: #1 Deepfakes, #2 ID document forgery, #3 Account takeover and Synthetic ID fraud. A pie chart shows 29% of successful fraud attempts use AI, while 71% are other types. Source: Signicat.

When GenAI emerged as a viable tech capability, businesses weren’t the only ones who went for it. So did cybercriminals who used the technology to create highly realistic deepfakes and pass Know Your Customer (KYC) onboarding at digital banks. Since the mass adoption of artificial intelligence, the number of AI-generated identity fraud cases in fintech has increased by 2137%. Now, 1 in 15 attacks involves deepfakes, and 29% of them succeed.

Our client, a Netherlands-based digital bank serving customers across the European Economic Area, chose to be one step ahead of fraudsters. As the bank onboards 4-5 million new users annually, they must protect real customers from account takeover, not to mention safeguarding brand trust in a highly competitive digital banking market.

At the time, the client relied on a third-party SaaS identity verification (IDV) platform with OCR and NFC/RFID technologies at its core, which fell short on several fronts:

  1. Failures in detecting AI-generated identity documents. Passports with AI-altered images or completely fake documents could pass through the checks if they visually match the templates of authentic IDs.
  2. Slow speed of adaptation to fraud patterns. The SaaS IDV was tied to the vendor’s release cycles, meaning weeks of waiting for new reported fraud cases to be updated in the system’s detection logic, while the new attack patterns kept snowballing.
  3. Limited control over the deepfake detection mechanism. The client’s team didn’t have direct access to the underlying algorithm and couldn’t strengthen the SaaS IDV’s forgery detection and analysis by training it on their own fraud samples.

For a bank operating at a multi-million-user scale, the gap between their needs and software capabilities posed significant financial and reputational risk. They needed a tech partner with proven expertise in finance to address the issue.

Solution

Instinctools’ dedicated team looked into ways to strengthen the client’s identity verification algorithm. Investing in a custom computer vision-based deepfake detection to run alongside the SaaS IDV proved to be the most beneficial option, as it enabled hotfixes and retraining on confirmed internal fraud cases within days.

Our computer vision experts took full ownership of the system’s design, training, calibration, and production rollout.

  1. Assembling a fraud-realistic dataset

The effectiveness of the custom CV detection mechanism hinged on the quality of the training data. Generic examples of ID fraud, that the off-the-shelf IDV platform had covered, were not enough. Therefore, our team prioritized assembling a solid dataset.

  • Doubling down on data preparation (exploration, cross-source collection, cleanup) to reduce training time.
  • Defining attack taxonomy that reflected the most relevant fraud patterns, from partial manipulations of photos, textual and numerical data to fully AI-generated documents.
  • Building a dataset that included the fake IDs the staff caught during KYC checks, partly and completely synthetic documents, and legitimate but low-quality photos and scans of passports.
  • Increasing the share of hard negatives in the dataset through data augmentation. Valid documents with blur, glare, or perspective distortion often triggered false alarms in the SaaS IDV platform, and we wanted to avoid this issue by training the custom CV algorithm to accurately distinguish poor capture quality from actual manipulation.
  • Labeling the data based on different criteria (real document vs. fake, fraud location, etc.).
  1. Designing an ID-focused CV pipeline

What is YOLO?

YOLO (You Only Look Once) is a computer vision object detection model. It’s an example of a leading-edge single-stage detector, known for its ability to locate and classify objects in a single pass through the network and, therefore, a go-to option for real-time object detection.

Our team built the solution around a single, well-controlled YOLO-based computer vision pipeline, tailored for identity document analysis. The model excels at:

  • Detecting the presence of a document
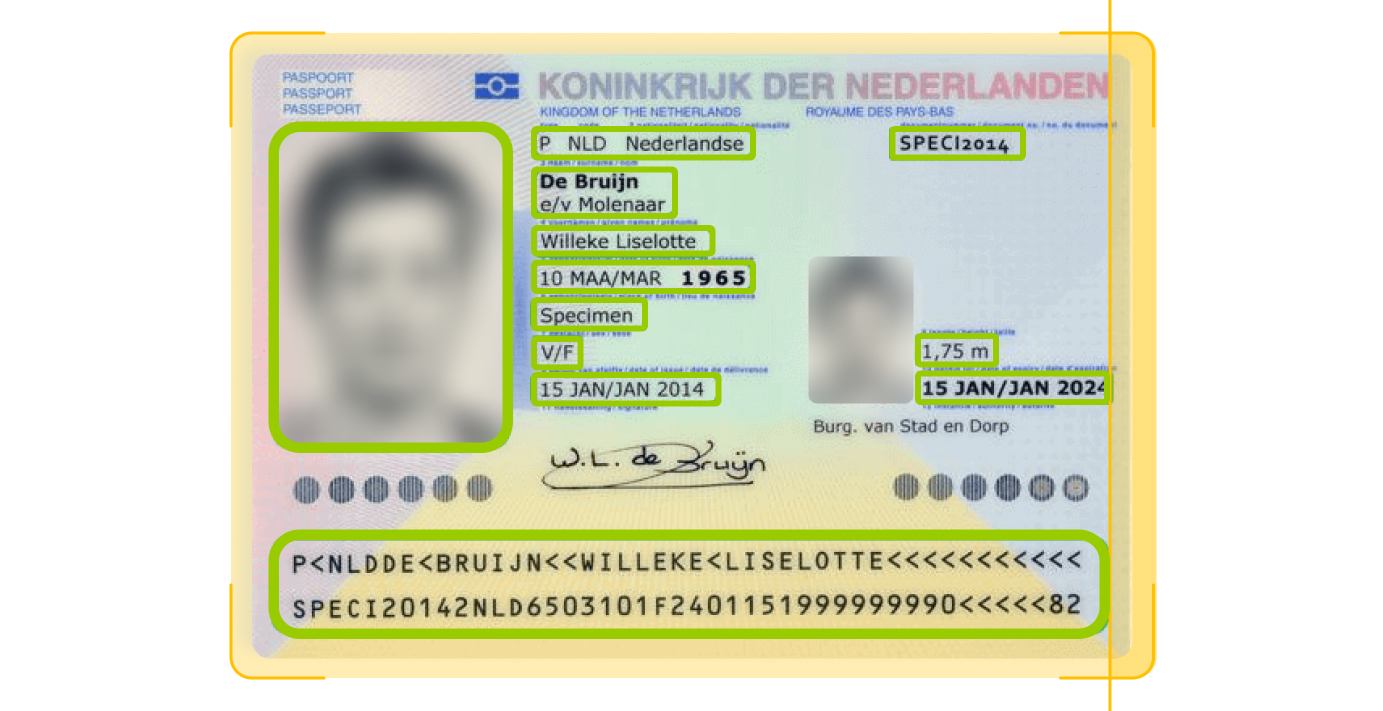
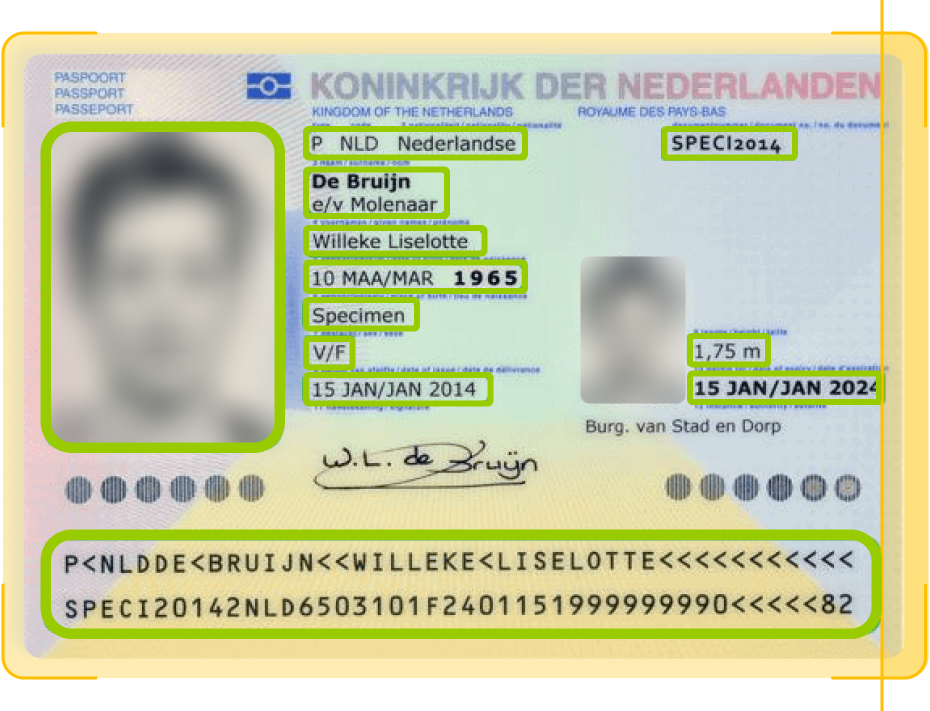
  • Localizing and analyzing in a single pass critical document regions, such as the data page, portrait area, and MRZ code
  • Highlighting suspicious area(s) of the document
  • Providing a risk score for each problematic element to simplify and speed up the review process

This approach ensured consistency while keeping inference fast enough for real-time KYC flows.

A sample Dutch passport shows personal details: a blurred photo, name “WiIieke Liselotte De Bruijn,” date of birth 10 March 1965, height 1.75m, and expiry date 15 January 2024. Text is in Dutch and English with blue and orange highlights.
A Dutch passport for Willeke Liselotte de Bruijn with personal details, passport photo, and security features. The passport text is in Dutch and English, and highlighted sections include name, birth date, height, gender, and document number.
  1. Ensuring the detection is reliable beyond known fraud patterns

To avoid building a system that works only for already known fraud tricks, we focused on how well the solution would hold up when attackers change their techniques and tools. Therefore, we deliberately checked it against document manipulations and generation methods it hadn’t seen before.

The test dataset included:

  • Data created by the same top 10 deepfake generation tools we used when assembling the training dataset, but with different faces and parameters
  • Data generated by other tools that weren’t used for creating the training dataset

This approach ensured the detection logic wasn’t tied to a specific deepfake tool or editing technique, but rather to the visual inconsistencies that tend to appear across AI-generated and manipulated documents, so the custom CV system remains effective even if fraudsters switch to new image generators.

  1. Decision threshold calibration

One of the key challenges with the SaaS IDV platform was the sensitivity of its fraud calibrator, which sometimes caused it to reject legitimate customers due to minor issues (like glare in a photo) while overlooking more serious fraud attempts. To address this problem, we linked the decision thresholds to the risk scores.

The custom CV layer now follows a tiered decision logic:

  • Low-risk cases continue through onboarding automatically, without any additional steps
  • Middle-risk cases trigger targeted step-ups, such as an NFC scan, requesting  an extra selfie or a short video
  • High-risk cases are flagged for manual review or outright rejection

This approach helped the client strengthen fraud controls and decrease the workload of human reviewers while ensuring fast onboarding for legitimate users.

  1. Seamless integration
of the CV layer into the client’s KYC flow

To keep the onboarding experience unchanged for customers, we deployed the custom computer vision system as a decision microservice within the existing onboarding pipeline. 

Still, before letting it influence real onboarding decisions, the team ran the custom CV system in observation mode. At this stage, it processed live KYC traffic alongside the existing systems, but its outputs were not used to approve or reject customers. 

Once we validated that the model behaved as expected with real-world data, we rolled it out gradually by feeding it controlled portions of traffic, expanding coverage step by step. This phased approach ensured that the new detection layer strengthened fraud controls without unintended consequences, such as over-flagging legitimate users or missing edge cases.

Here’s how the client’s updated KYC flow works:

  1. A user submits their documents (and, if required, a selfie or short video)
  2. The existing SaaS IDV platform performs its standard checks, such as OCR, MRZ reading, and NFC validation
  3. The custom computer vision system analyzes the same inputs in parallel
  4. The higher-level KYC orchestrator then collects and combines the results from both systems and applies the bank’s decision logic to determine the next action (approval, step-up verification, or manual review)

Since all checks run behind the scenes and in parallel, customer experience stays the same, with no extra waiting time or redundant requests. Meanwhile, under the hood, confirmed fraud cases are auto-labeled and folded into retraining cycles within days, enabling hotfixes. As a result, deepfake document detection had shifted from a static vendor capability to a living, bank-owned system evolving at the same pace as the threat landscape.

Before

  • Deepfake document detection depends entirely on a third-party SaaS IDV platform
  • AI-generated or partially manipulated documents highly resembling valid ID templates the SaaS platform was trained on could pass checks, while low-quality documents from real customers could have been rejected as synthetic
  • Time-intensive manual reviews due to the software’s unreliability
  • Weeks-long response to new deepfake techniques due to vendor-controlled update cycles

After

  • Custom, bank-owned computer vision layer added on top of the existing SaaS IDV platform
  • The CV system is trained on a high-quality dataset and follows tiered decision logic to perfect deepfake detection without affecting legitimate customers
  • Reduced review workload on the humans in the loop thanks to the well-calibrated decision logic
  • Adaptation to new deepfake patterns within days thanks to hotfixes

Business value

  • + 30% in detected synthetic document fraud
  • – 60% falsely flagged legitimate users
  • – 40% in manual review workload

Client’s testimonial

Multiplier effect

Computer vision threat detection use cases extend far beyond digital banking. Any company that relies on document checks or user verification, from insurance and healthcare to travel and ecommerce, faces the same growing risk from AI-generated identities and forged documents. A custom computer vision system trained on real-world fraud patterns can help businesses react faster than when relying on generic vendor tools.

A person in a dark blue shirt holds a smartphone in one hand and types on a laptop with the other. Digital facial recognition icons and a checkmark appear, indicating successful facial authentication on the phone. The background is blurred.

Computer Vision Defect Detection

Computer Vision Defect Detection For an Electronics Manufacturer

How switching from a rule-based machine vision system to an advanced computer vision solution for early-stage defect detection on the production line helped an electronics manufacturer reach 97,4% accuracy in identifying flaws and save $2.4 million annually thanks to a drop in warranty claims.

Business challenge

Our client is a Saudi-based electronics manufacturer producing laptops for the MEA region in partnership with one of the global tech leaders. Years earlier, we had created digital twins of their factories, so when new challenges surfaced, the client turned to us again. 

The company had long moved from fully manual defect detection on the production line to an automated, non-contact product quality inspection. However, their automated optical inspection (AOI) in the conveyor video surveillance system was too demanding, rigid, and costly, posing numerous limitations. 

  • Overdependence on consistent imaging. The system cannot function efficiently if lighting and camera positioning aren’t stable.
  • Inflexibility. AOI operated on strict “if-else” rules, making the system unable to perform continuous trend analysis and adjust dynamically to enhance both speed and accuracy of defect detection. 
  • Slow adaptability. Every time the component configuration, size, or color changed, the system required recalibration. 
  • Low scalability. One AOI system couldn’t simply be replicated across multiple factories. Each production line will require extensive manual parameter tuning. 
  • Costly maintenance. Traditional machine vision systems like AOI require highly specialized experts to take over routine manual inspections, regular calibrations, software updates, and hardware repairs. 

The client needed a more flexible, scalable, and budget-wise form of computer vision at the core of their conveyor video surveillance system.

Solution

Our development team ensured the smooth shift from basic AOI to advanced computer vision.

  1. Shaping up the tech stack

We decided to rely on a pre-trained object detection and image classification model. Then, we had to choose between single- and two-stage detectors to perform object detection. The scale was tipped in favor of a single-stage algorithm due to its several advantages:

  • Faster inference
  • Lower computational demand
  • Easier maintenance

Having experience with various single-stage detectors, we settled on YOLO over CenterNet, SSD, RetinaNet, and FCOS, as it offers superior inference speed, ensuring truly real-time performance. Despite YOLOv10 being available, we used YOLOv8, as it was the most tested and stable version at the moment.

  1. Optimizing the training dataset

The client’s previous pre-computer vision system relied on a three-tier defect classification framework: “definitely defective,” “borderline,” and “definitely non-defective”. Rather than discarding the existing dataset, we capitalized on it by strengthening defect coverage and enforcing consistent, high-quality labeling.

Augmenting data to address the class imbalance issue

The original dataset was limited in size, with a maximum of 200 images per defect category. In addition, different defect types weren’t represented equally. For example, issues such as missing components and incorrect placement appeared far more frequently than subtler issues like misalignment, solder defects, open circuits, or lifted leads.

To address both the small dataset size and class imbalance, we applied data augmentation techniques:

  • Random photo cropping and flipping
  • Controlled blurring and noise injection
  • Tweaking lighting
  • Changing the background

That way, we multiplied the dataset tenfold while ensuring balanced representation across all defect categories.

Improving labeling consistency and reliability

Given the diversity of subtle defects, high-quality labeling was a must-have. Our AI engineers focused on refining the labeling process to: 

  • Reduce annotation noise
  • Improve consistency across classes
  • Enable more statistically reliable quality assessments

In addition, we ensured the dataset included images both with and without the target object, improving the model’s ability to distinguish true defects from background artifacts and, thus, reducing the false positive rate.

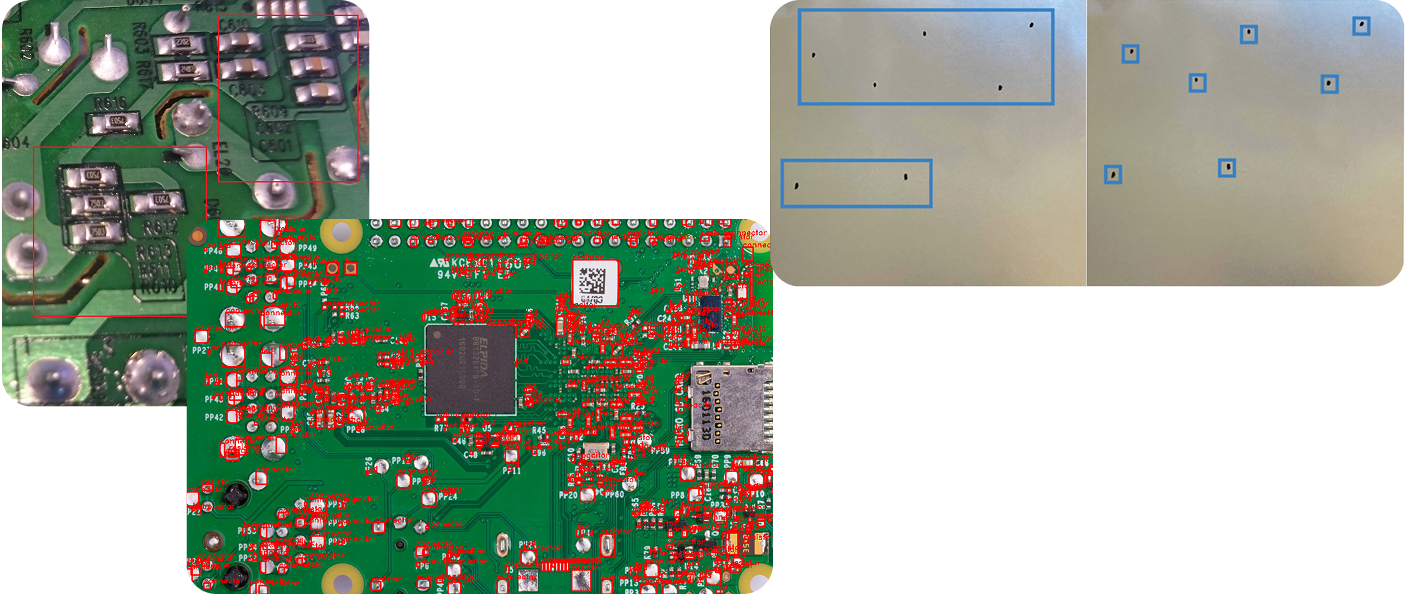
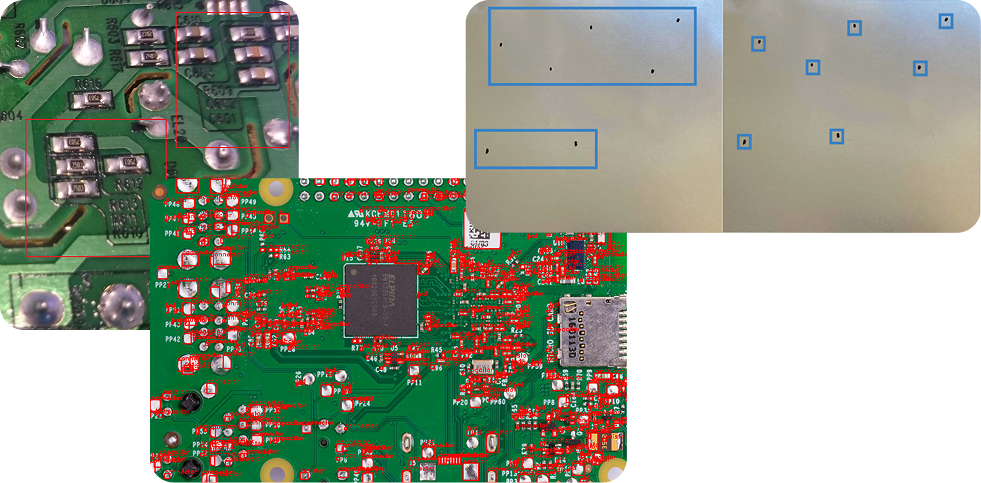
A collage showing two close-up images of green circuit boards with various electronic components and solder points, and one image of a metallic surface with blue rectangular and square outlines marking different areas. Text is faintly visible in the bottom right corner.
Three images: a close-up of a green circuit board showing silver solder joints; a larger green circuit board with many red and silver components and a central microchip; and a metallic panel with blue-outlined rectangular and square cutouts.

More consistent labeling enhances the reliability of bounding boxes, teaching the model to distinguish every little part and defect as a separate entity, rather than group several objects within a single bounding box.

A collage of three images shows close-ups of green circuit boards with red components and microchips, overlaid with a photo of a metal plate featuring multiple cutouts and small square and rectangular holes highlighted in blue.
More consistent labeling enhances the reliability of bounding boxes, teaching the model to distinguish every little part and defect as a separate entity, rather than group several objects within a single bounding box.

  1. Running model transfer learning on the enhanced dataset

Models for object detection and classification like YOLO are already trained on hundreds of millions of general images. However, to accurately address the client’s specific needs, it had to undergo additional training on the updated dataset.

Instinctools’ AI engineers took an efficient approach to tackle this challenge. They resorted to transfer learning as an ML training technique to improve the model’s performance:

  1. Started with a pretrained YOLO model
  2. Used PyTorch to remove the default classifier head
  3. Replaced the model’s classifier head with the enhanced dataset

After that, YOLO was able to instantly detect and classify all the specific defects relevant to the client’s production line.

What is transfer learning in computer vision?
 
Transfer learning is a machine learning training technique, which capitalizes on the pre-trained model’s general knowledge (the ability to detect different defects on various surfaces) instead of training the model from scratch.
 
With transfer learning, you only retrain the model on your task-specific dataset (examples of external and internal defects of the client’s laptops), enabling the model to adapt its existing knowledge to your reality. This method significantly reduces training time and computational resource consumption.
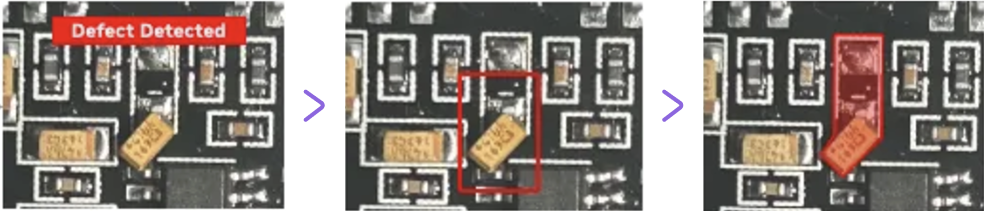
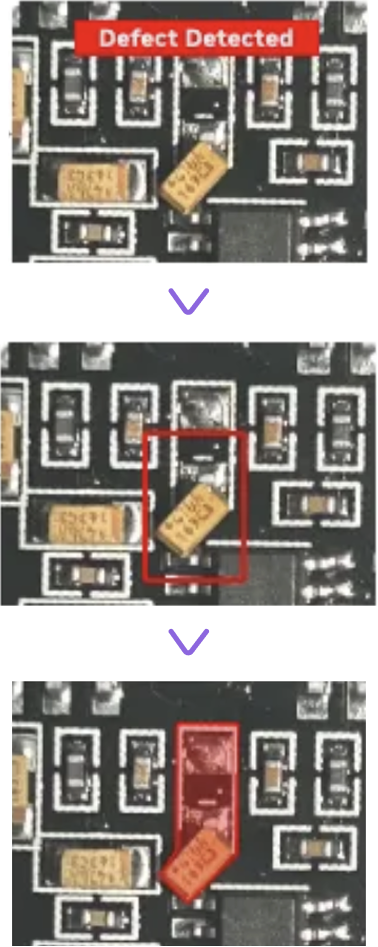
Three images show a circuit board section. The first has a red “Defect Detected” label, the second outlines a component in red, and the third highlights the component with a red overlay, indicating the defect’s location. Purple arrows separate each step.
Three stacked images of a circuit board: 1. Top image highlights a component with a red “Defect Detected” banner above. 2. Middle image shows the same area outlined with a red box. 3. Bottom image shades the component in red, marking it as defective.
  1. Calibrating defect inspection thresholds 

Defining a defect is only part of the process. Next, our dedicated team helped minimize the number of items wrongly discarded at the production stage through:

  • Raising a confidence threshold ratio from 0.5 to 0.85 to prevent the model from flagging low-certainty cases as sure defects 
  • Setting up detailed defect severity scoring to minimize false positives while not letting critical defects slip further
  • Adjusting NMS (Non-Maximum Suppression) parameters so that the model always chooses one clean, highest-confidence box per object instead of overlapping bounding boxes
  1. Going the extra mile for near-100% defect detection accuracy 

After transfer learning and threshold calibration, the model’s accuracy reached 86,5% which was already more than 15% higher than with the previous AOI system. Still, our team aimed for as close to 100% accuracy as possible.

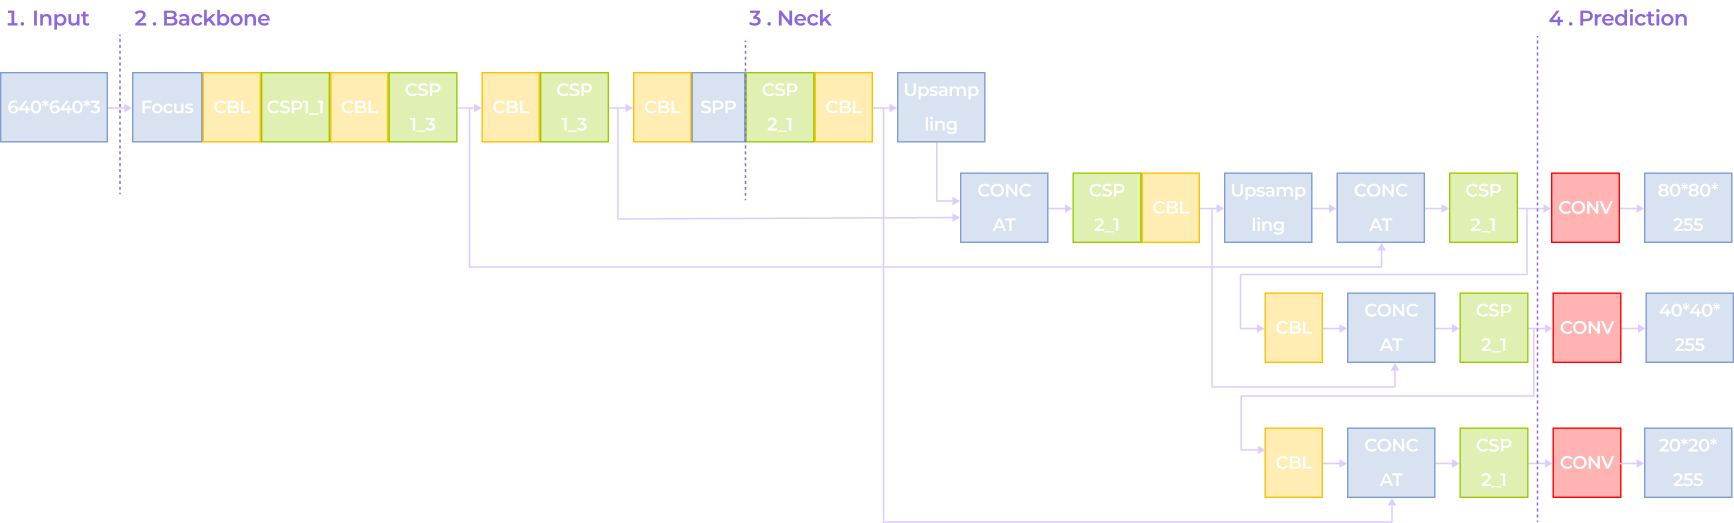
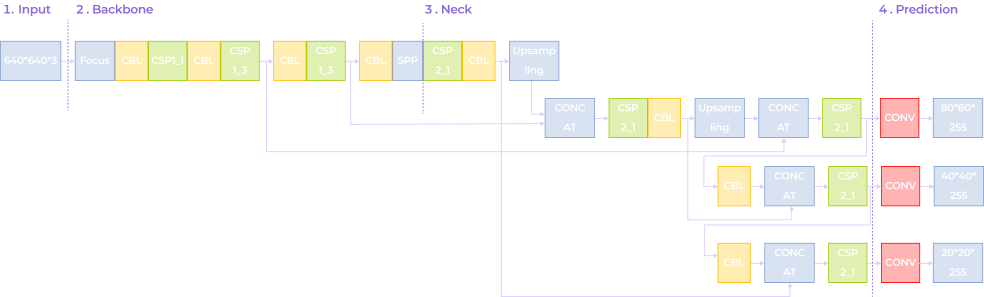
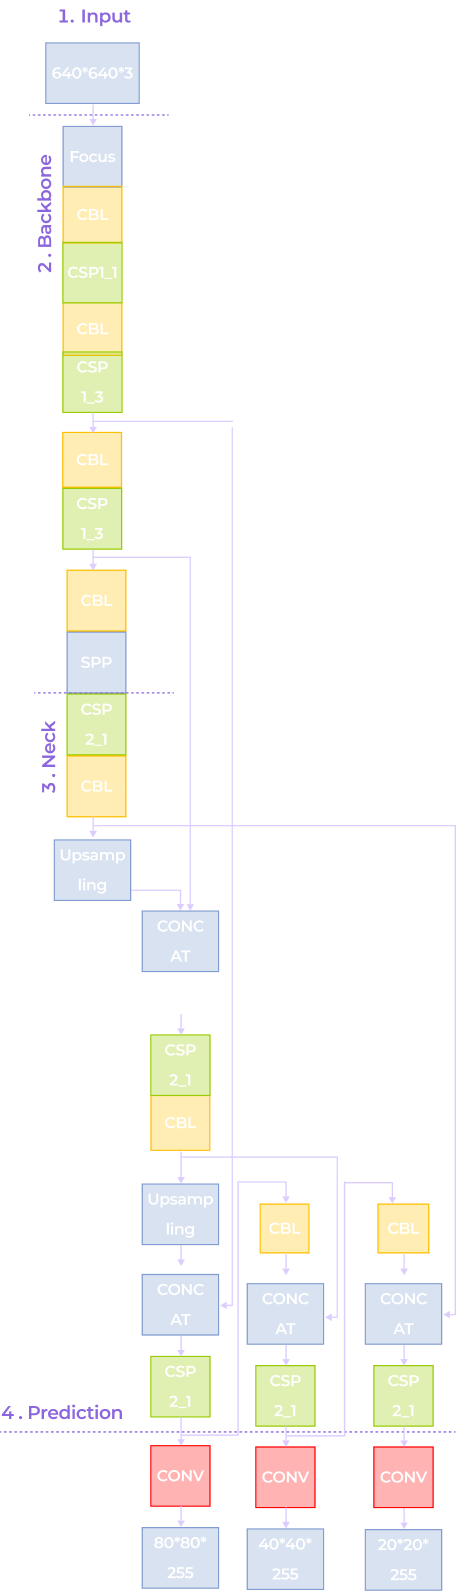
Instinctools’ AI experts enhanced YOLO-based defect detection capabilities by applying:

A flowchart showing a neural network architecture with four stages: Input (640x640x3), Backbone, Neck, and Prediction. Colored blocks represent layers like Focus, CBL, CSP, SPP, and CONV, with branching paths for multi-scale predictions.
A flowchart of a neural network architecture with four sections: Input (640x640/3), Backbone (Focus, CBL, CSP, SPP), Neck (CSP, Upsampling), and Prediction (Conv layers with outputs: 80*80/255, 40*40/255, 20*20/255).
A vertical neural network diagram with four labeled sections: Input (640×640×3), Backbone (Focus, Conv, CSP1, SPP), Neck (Upsampling, Concat, CSP2), and Prediction (Conv layers with outputs: 80×80×255, 40×40×255, 20×20×255).
  • Depthwise Separable Convolution (DSConv) to accelerate the model’s inference speed
  • The Cross-Stage Partial Network (C3 module) to combine low-level detailed information with high-level semantic data, enhancing the model’s adaptability to target scale variations and improving detection accuracy
  • The Bidirectional Feature Pyramid Network (BiFPN) to enable the model to identify fine features of small targets, improving its recognition capability
  • The DySample upsampling operator to minimize detail loss and boost accuracy for small targets

With these enhancements, the new CV defect detection system consistently hits the 97,4% accuracy benchmark.

  1. Integrating the CV mechanism into the client’s manufacturing execution systems (MES)

The computer vision solution was installed at one of the client’s facilities. There, it underwent further model training based on collected metadata and outputs generated by the system during operation. Those adjustments helped align the system with real-world production conditions and replaced AOI at each critical juncture:

  • Post-solder paste application. The system verifies if paste volumes are adequate and properly aligned.
  • Post-component placement. The solution validates whether each component is present, oriented correctly, and positioned within acceptable tolerances.
  • Post-reflow. Software runs a final check for defects such as tombstoning, bridging, and cold solder joints.
The result is an all-encompassing, multi-class defect classification, with all defects categorized by type and severity.
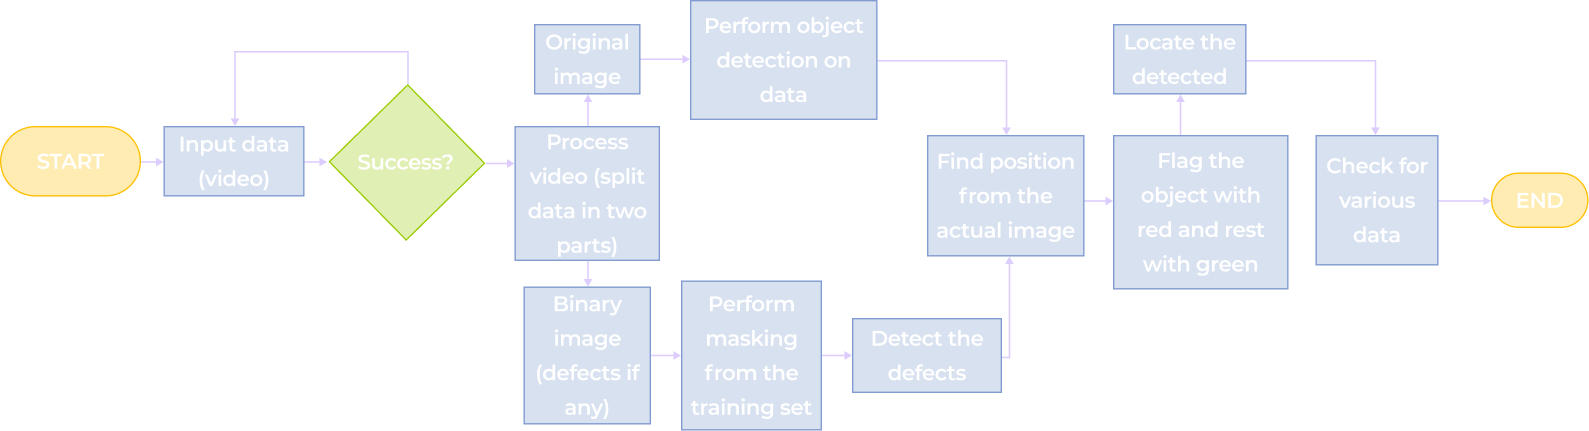
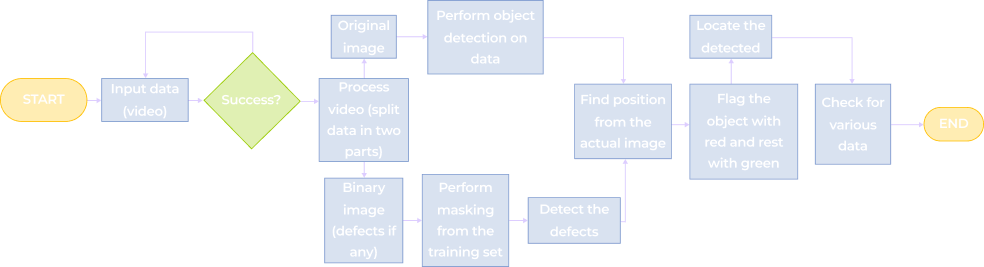
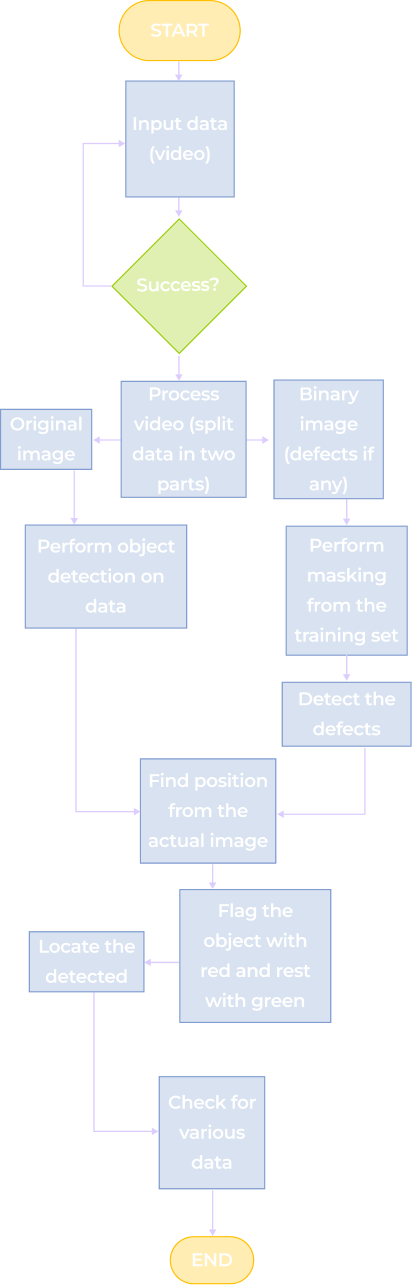
A flowchart for video object detection: Starts with Input data (video), checks Success?, then branches to process the image or video, detects defects, locates them, flags with red and green, checks for various actions, and ends the process.
A flowchart for object detection in video: start with video input, check for success; if yes, process original image and video; create binary image, mask defects, then perform object detection, locate defects, flag objects, and check results to end.
A vertical flowchart shows steps from inputting video data, processing and splitting the video, detecting objects and defects, flagging objects, checking data, and ending. Steps are in colored rectangles with directional arrows connecting them.

As the solution features cloud connectivity, our team can remotely perform model updates, configuration changes, and CV algorithm optimizations. 

Before

  • A rigid and costly machine vision system that has to be configured for each production line
  • Real-time defect detection is only possible under perfectly stable lighting 
  • 70% accuracy of defect detection
  • Items falsely discarded as defective

After

  • Flexible and highly scalable computer vision system that can be reused across production lines
  • Real-time defect detecting under any lighting conditions
  • 97,4% accuracy of defect detection
  • < 0,5% discarded items

Business value

Operational impact:
  • + 27,4% accuracy of production line inspections 
  • + 24% in production throughput due to immediate defect detection
  • < 2% false positive rate
  • < 0,5% discarded items 
  • – 67% defect-related warranty claims
Financial impact:
  • – $1.2 million in waste-related costs
  • + $2.4 million annually due to the drop in warranty claims 
  • – 26% in quality control labor costs

Client’s testimonial

Multiplier effect

Stronger quality-control systems on a production line lead to fewer defective products reaching customers and ruining their experience. With the stakes as high as one in three customers* leaving a brand after a single bad experience involving defective products, playing it safe becomes essential for business survival.

Computer vision can be the key to achieving higher-quality products and improved customer satisfaction. 

*According to PwC

A diverse group of six people sit around a table with papers, coffee, and devices, engaged in discussion. Overlaid text reads Customer Feedback: Connect with your friends. Notification icons and messages appear around the image.

AI Agents-Based Customer Support For an Online Store

AI Agents-Based Customer Support For an Online Store Serving 3+ Million Customers Yearly

How delegating the support ticket triage groundwork to an AI multi-agent system empowered a US online store to process support requests 4 times faster and accelerate first-response time by 75% without hiring more customer support specialists.

Industry:
Ecommerce

AI Development

Business challenge

When the number of customer support requests hits 5,000 per day and spikes up to 10,000 on Black Friday and holidays, mostly manual handling becomes a bottleneck. Delays, inconsistencies, and escalating costs snowball by the day. Our client, a US-based online store with over three million shoppers, felt the pressure where it hurt most: in operational efficiency and customer satisfaction score (CSAT).

What issues pushed them to look beyond simply hiring more people?
Slow and costly process

On average, consumers expect their query to be answered within 5 minutes*. In the client’s case, the waiting time could stretch to 12 minutes. This gap put the online store at risk of losing half their customer base, as only 1 in 2* shoppers is willing to stay with the company after a single poor support experience.

*According to Zendesk

Operational capacity lagged far behind demand on all fronts. Besides spending 6–12 minutes per request, the client’s support specialist managed to process only 50–70 tickets daily. Meanwhile, to satisfy the demand, they needed to cover 200+ tickets daily and at a much faster pace. Tripling the headcount might have closed the volume gap, but this costly measure still wouldn’t resolve the slow response time issue.
Error-prone ticket categorization and prioritization

Human agents sometimes mislabelled issues or overlooked important details when prioritizing tickets. These mistakes affected the first-response time, as the requests had to be recategorized and re-prioritized.

Slow knowledge scalability

Each time new communication guidelines, return and refund policies, and other updates came in, customer support staff needed time to adjust their daily routine accordingly.

The client considered using AI virtual workers to address the pressing issues, but needed a reliable AI engineering partner to act on the idea. Inctinctools proved to be the one up for the task and assembled a dedicated team of AI engineers, QA specialists, and a project manager.

Solution

Among the many forms AI virtual workers can take, we selected microservices-based agentic AI to transform the client’s customer support.

AI agents facilitate:

  • Real-time ticket triage. Tickets are categorized and routed in milliseconds upon arrival. Urgent issues are instantly flagged, improving the time to response.
  • Consistent categorization and prioritization. AI agents treat every ticket objectively against the same standards, reducing errors​.
  • Always up-to-date expertise. New guidelines, policies, and rules are embedded in the AI models’ databases and apply to support requests instantly.

Microservice architecture, where each agent is implemented as an independent microservice, enables:

  • Fast development. The dedicated team can craft several AI agents in parallel.
  • No tech stack lock-in. AI engineers build each agent using the ML models, programming languages, and libraries best suited for a particular role.
  • On-demand system scalability. Microservices auto-scale up and down, readjusting to the workload, and can process thousands of tickets per minute.
  • High system stability. If there’re issues with one of the AI agents, it can be isolated without bringing down the whole system.

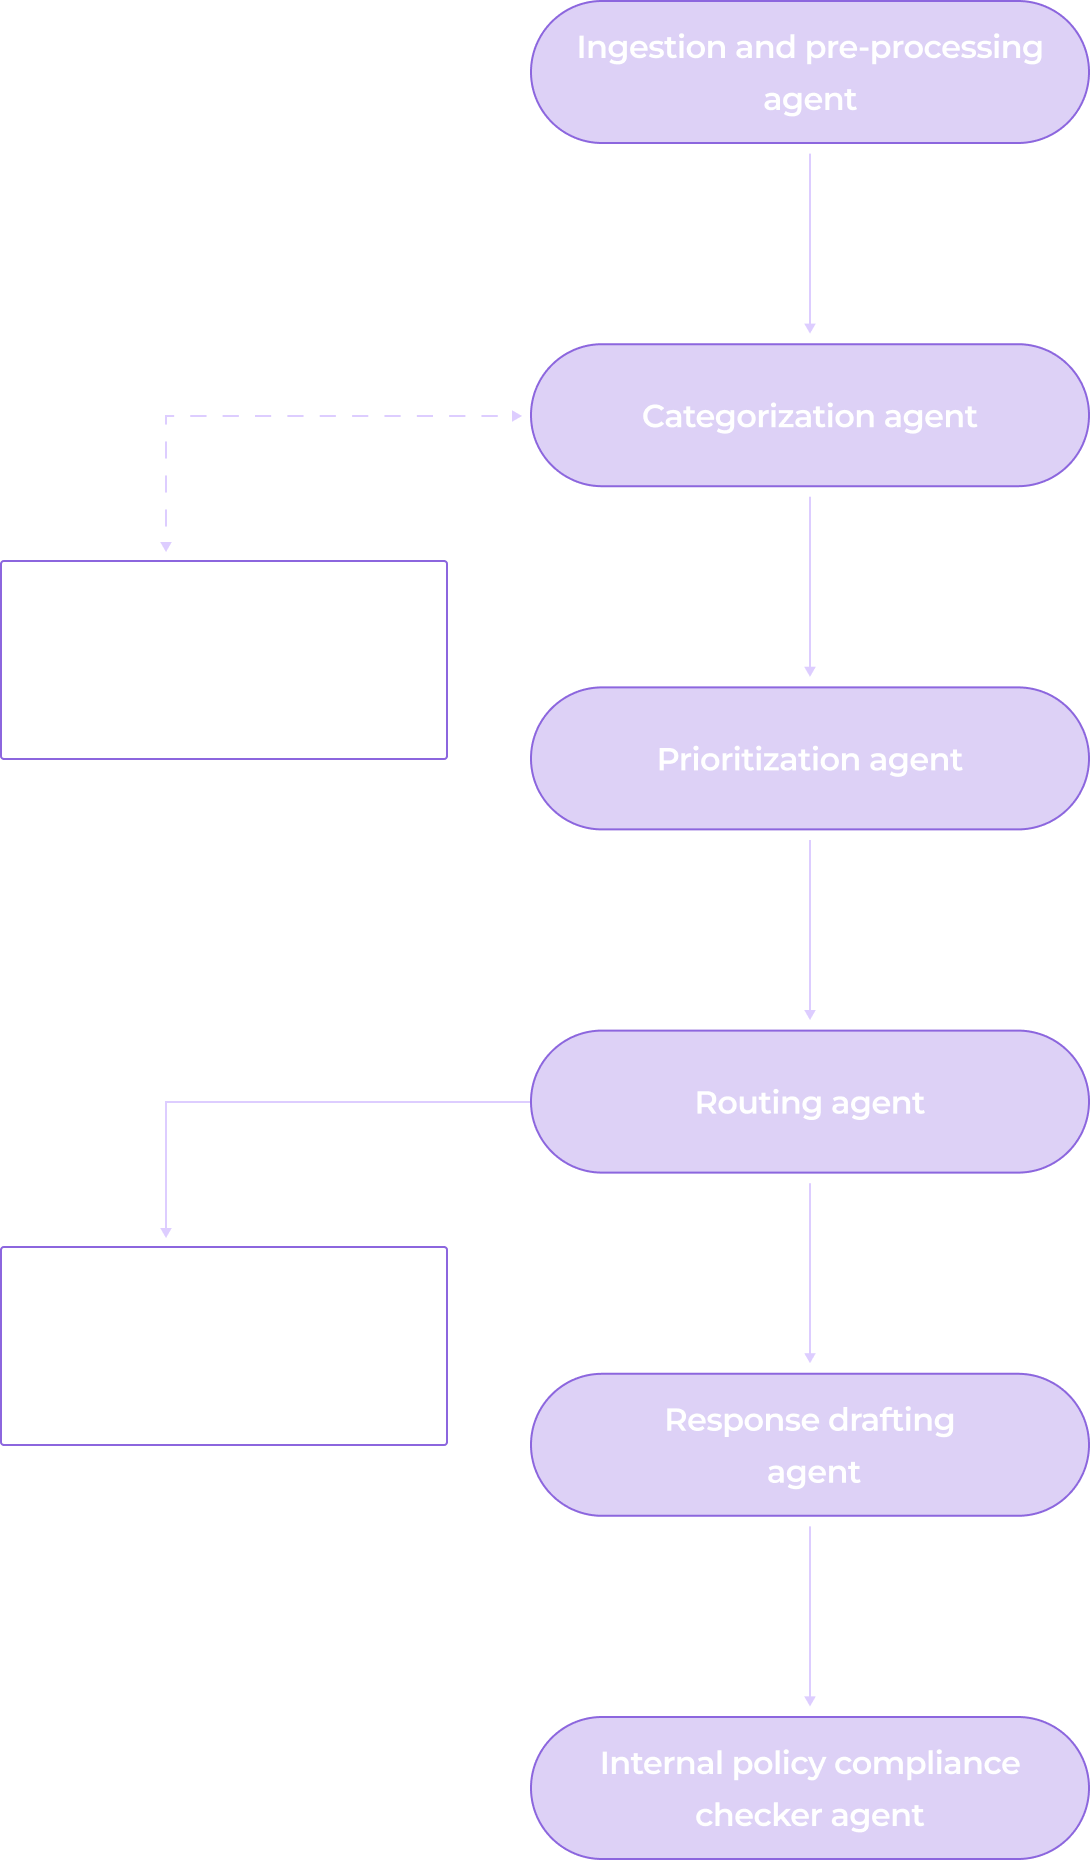
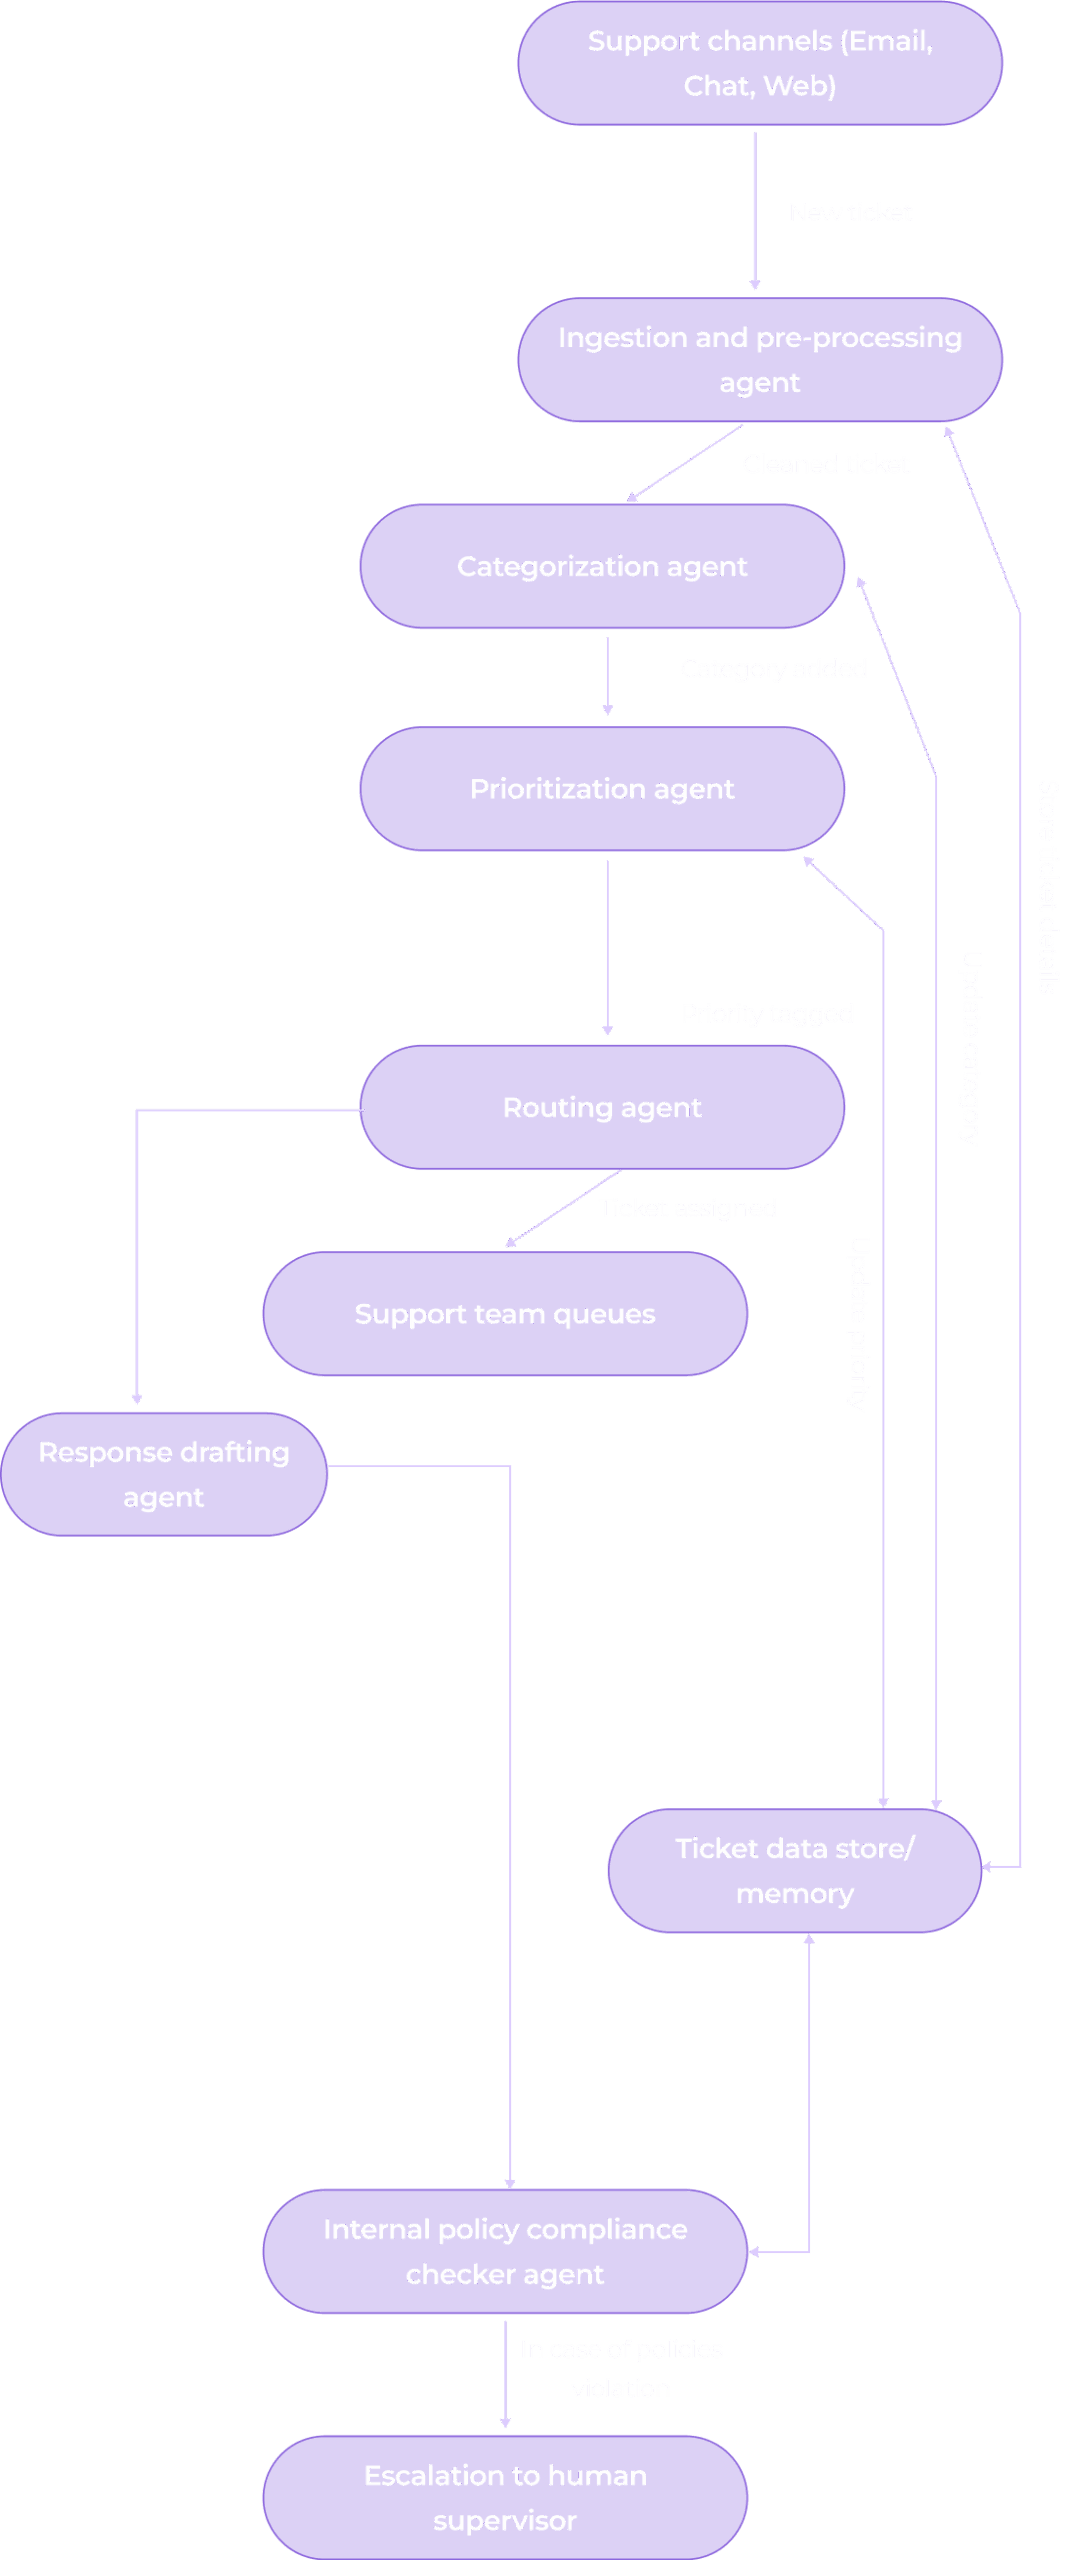
After analyzing the client’s customer support workflow, we suggested crafting six AI agents working within a multi-agent (MAS) pipeline:

  1. An ingestion and pre-processing agent removes personally identifiable information (PII) and other sensitive data and attaches metadata important for prioritization, such as account tier.
  2. A categorization agent analyzes the request and puts it into a relevant issue category, say, ‘wrong product,’ ‘delivery status,’ ‘billing issue,’ etc. If the query doesn’t fit the existing taxonomy, the agent escalates the ticket to human supervisors.
  3. A prioritization agent checks the text for urgency markers (words and phrases such as ‘ASAP,’ ‘immediately,’ ‘I’ve already written five times about this,’ etc.), factors in metadata from the ingestion agent, and assigns priority level from P1 (Critical) to P4 (Low).
  4. A routing agent determines which of the available support teams or individual agents fits best for addressing the issue and assigns the task.
  5. A response drafting agent outlines a preliminary answer to the customer’s query.
  6. An internal policy compliance checker agent inspects whether the proposed response aligns with the company’s guidelines on communication with customers and other policies applicable to the issue, for example, return and refund rules.
A vertical flowchart with purple rounded rectangles showing steps: Ingestion and pre-processing agent, Categorization agent, Prioritization agent, Routing agent, Response drafting agent, and Internal policy compliance checker agent. Side arrows point to Human agents and Support teams.
  1. Data classification and model training

Most AI agents mentioned above were trained on thousands of past customer support tickets. However, training the internal policy compliance checker required a different approach. There simply weren’t enough examples of requests that violated the company’s guidelines to train the model effectively. To solve this, we generated a synthetic dataset of 2,000 conversations that deliberately broke internal guidelines around customer communication, returns and refunds, accessibility and inclusion, and other policies.

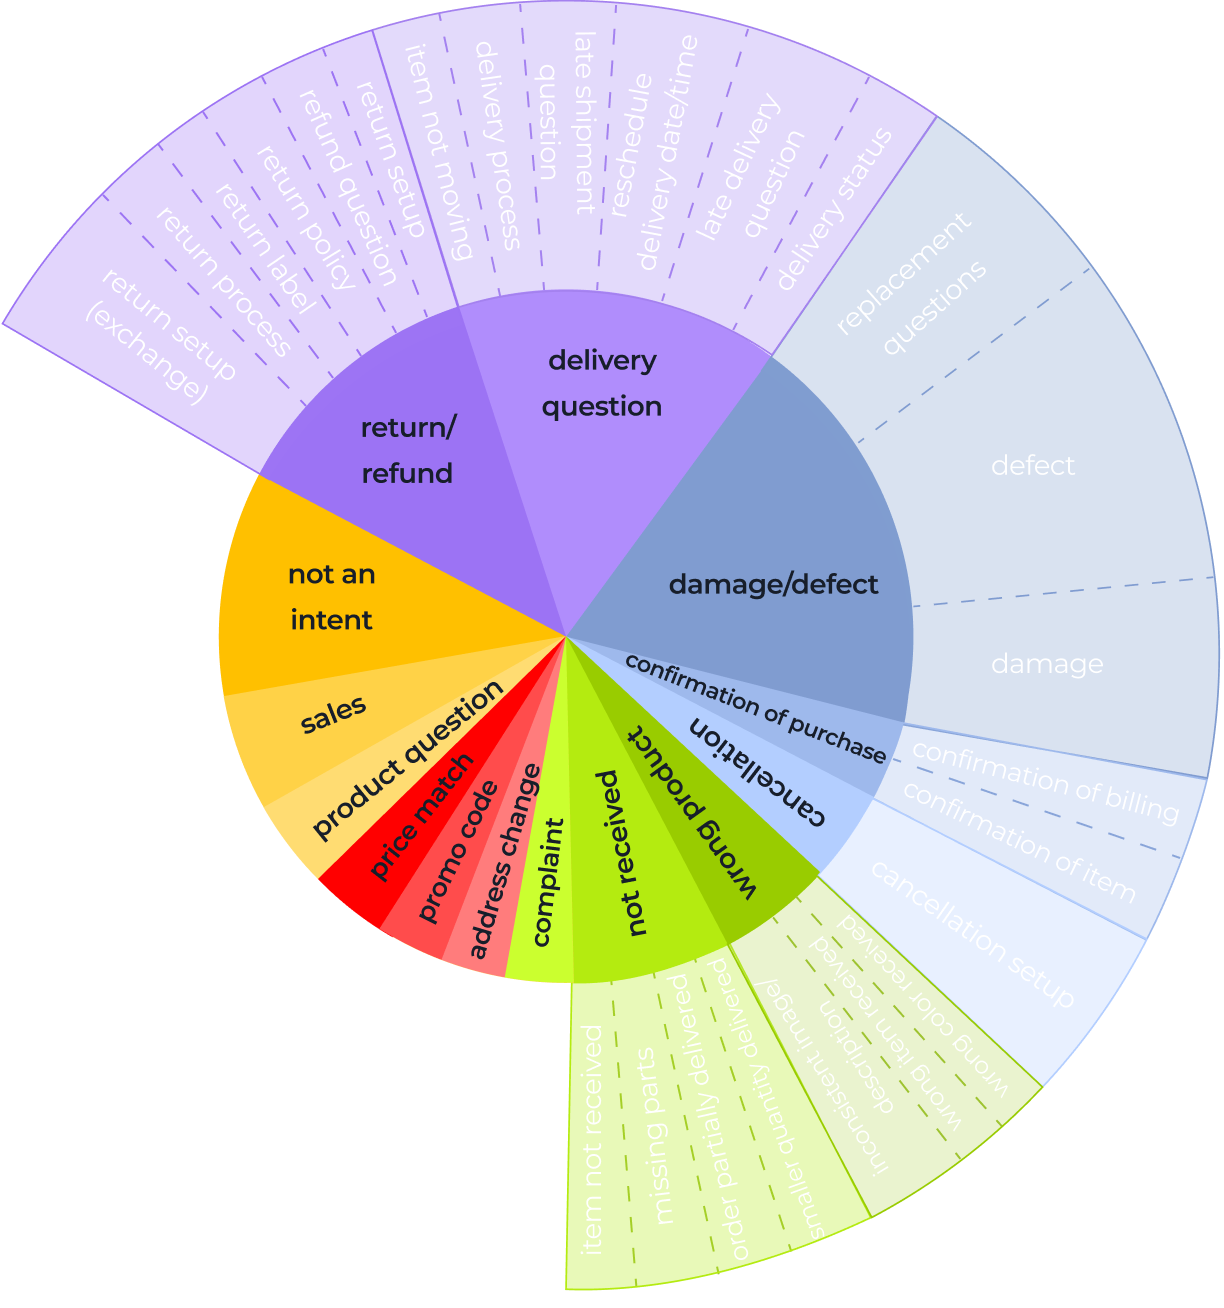
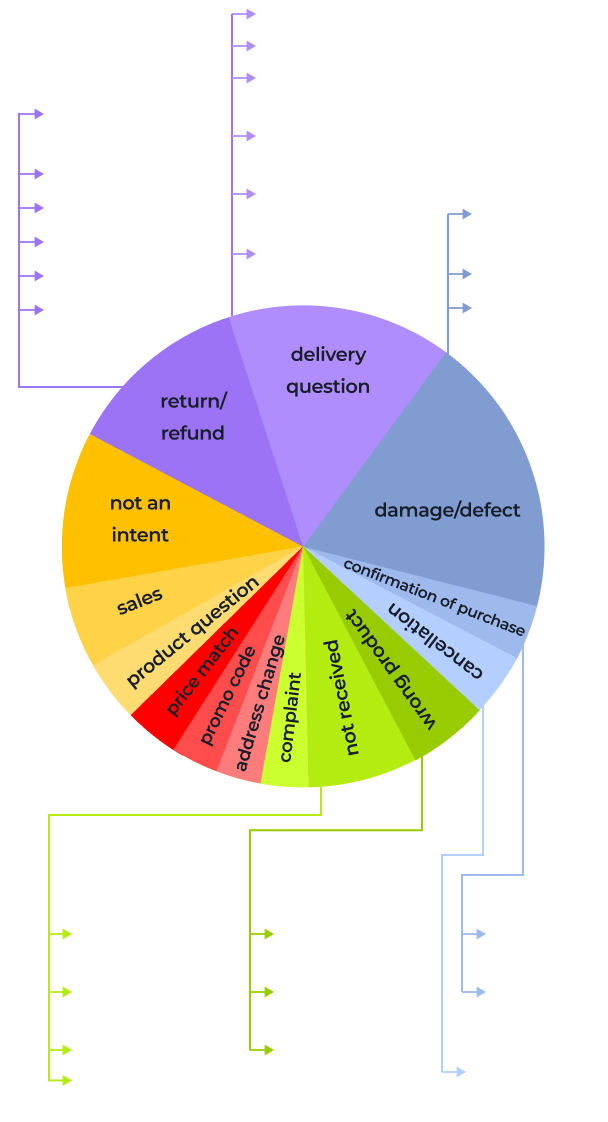
Once the datasets were ready, our team took on data analysis, classification, and labeling to create high-quality datasets for ML model training. As a result, we got a clear picture of the 14 broad categories of customer support requests with 75 subcategories.

A colorful, segmented radial chart shows customer inquiry categories, including delivery, returns, product issues, sales, and complaints, with each main category branching into specific topics such as return setup, product details, damage, cancellation, and billing.
A colorful pie chart categorizes customer inquiries: return/refund, delivery question, damage/defect, wrong product, not received, complaints, price match, product question, and sales. Each segment lists specific issue types, connected by lines with brief descriptions.

The labeled and categorized data then served as the foundation for training the ML models at the core of AI agents. We decided to leverage the pretrained models.

GPT was a perfect fit for drafting a response agent, as the LLM excels at generating polite and brand-safe answers out of the box.

BERT was a natural starting point for the other tasks, given that the model was already trained on the BookCorpus of 800M words and can outperform models like Claude, Llama, Mistral, and others on sentiment analysis tasks.

Nevertheless, BERT didn’t cut it as its inference speed (350 ms) wasn’t fast enough to ensure a seamless customer experience. Therefore, we reevaluated available ML models and switched to DistilBERT, which retains 97% of BERT’s language understanding but is 60% faster. In reality, the new model showed even better results — we decreased the inference speed to 98 ms.

Moving further, we evaluated the model’s performance. 
It showed 87% accuracy in categorization, prioritization, routing tasks, and policy compliance checks.

While this level of accuracy was sufficient, we didn’t stop there and leveraged retrieval augmented generation (RAG) to raise the bar even higher. For instance, we enabled more dynamic, context-aware reactions by allowing DistilBERT to access product reviews in real time. The accuracy of AI agents’ outputs spiked to 92%.

  1. How our AI multi-agent system works in practice

Here’s an example of our MAS handling a customer request.

A flowchart illustrates a customer support process, showing steps from support channels through ingestion, categorization, prioritization, routing, response drafting, policy checking, and possible escalation to a human supervisor. Steps are shown in rounded purple boxes.

A VIP customer wrote to customer support on the website:

Hello, I placed an order two weeks ago. #382911-A, under [email protected]. The tracking still says ‘label created’. I just checked my credit card statement and I’ve been charged twice — once on May 8 and again on May 9. My card ends in 3711. What’s going on? Better sort it out fast.

The ingestion and pre-processing agent removes the email and card’s last digits as it’s either personal or sensitive data. It also identifies the VIP account tier and attaches the corresponding meta tag to the request.

Moving further, the categorization agent identifies intent as billing issues and delayed shipment.

Next, the prioritization agent steps in and factors in metadata and urgency indicators in the customer’s request, such as “better sort it out fast.” Coupled with the VIP status, this ticket gets the highest priority level – P1.

From there, the routing agent takes on and finds the right team to resolve the customer’s issues. Since there’re two problems, it auto-creates two linked sub-tickets and routes them to the billing and logistics departments.

The response drafting agent generates a clear, action-oriented message designed to restore trust and resolve the issue quickly:

Hi Jane, thanks for reaching out, and I’m really sorry for the confusion and delay. I’ve located your order (#382911-A) and escalated it to our billing and logistics teams for immediate review. It appears you were accidentally charged twice, and we’re processing a refund for the duplicate charge. You’ll receive confirmation shortly. Meanwhile, I’ve flagged your shipment for manual tracking so we can get it moving ASAP. Thanks again for your patience — we’re on it!

The internal policy compliance checker agent verifies that the tone of voice adheres to brand standards, no PII is exposed, the refund policy is mentioned accurately, and handles the draft to a human in the loop.

All these operations, that previously took 6–12 minutes per each request, are now done within 
one (!) second. The customer support specialist only needs 1–3 minutes to review the AI-generated message and fine-tune it, if needed.

Such well-orchestrated human-AI agents collaboration enabled the client to reduce ticket handling time by 75%. An unaided support specialist could process a maximum of 70 tickets daily. With AI agents covering the groundwork, humans now each manage up to 250 tickets a day within the same working hours.

Before

  • Human error-prone support request categorization, prioritization, and routing
  • Ticket processing time is 6–12 min
  • A single customer support specialist can process 50–70 tickets daily, depending on their complexity
  • Need to triple the headcount of their support team to tackle the rising number of requests efficiently

After

  • Near-zero error rate at any stage of support request processing
  • Ticket processing time is 1–3 min
  • With an AI multi-agent system handling the groundwork, 
a single customer support specialist can now process 200–250 tickets daily
  • Support team seamlessly handles 4 times more tickets within the same working hours

Business value

  • Real-time ticket triage that was beyond the reach of mostly human-led customer support
  • ×4 faster overall support request processing without increasing the number of customer support specialists
  • 75% reduction in first-response time
  • 15% CSAT uplift

Multiplier effect

Customer support isn’t just a service touchpoint. It’s what turns one-time buyers into repeat customers. In fact, 93%* of consumers are more likely to make repeat purchases from companies that offer excellent customer service.

*According to HubSpot

This impact goes far beyond retail. For companies from any industry, from healthcare to banking to logistics, the speed, quality, and responsiveness of customer support directly affect customer retention, operational efficiency, and overall business profitability.

AI agents offer a smart and cost-effective path forward, helping companies scale support operations without growing headcount.

A person in a suit points at a glowing virtual button labeled “AI Agents,” surrounded by hexagonal icons with “AI” connected by digital lines, representing artificial intelligence networking and technology integration.

AI Virtual Assistant For a Travel App

AI-Fueled Virtual Assistant For a Travel Planner App

How upgrading their existing travel planner app by replacing a basic rule-based chatbot with a powerful AI-driven virtual agent enabled a GCC-targeted travel and hospitality agency to unlock hyper-personalization, resulting in a 15% increase in booking conversions and a boost in the annual retention rate from 28% to 41%.

Industry:
Travel and Hospitality

Software Product Development

AI Development

Business challenge

Just as the introduction of jet engines disrupted the travel industry in the 1950th, generative AI keeps thriving and upending travel planning in the same fundamental way. What’s more, conversational AI is also gaining momentum, ushering in a new era for customer experience. With the joint power of conversational and gen AI, previously reactive rule-based chatbots can be replaced with intelligent and proactive virtual assistants smart enough to act on the user’s behalf.

Our client, a digital travel and hospitality agency in the GCC region, didn’t miss a bit. With a wide partner network spanning local airlines, hotels, taxi services, cultural venues, restaurants, etc., they jumped at the chance to pull ahead.

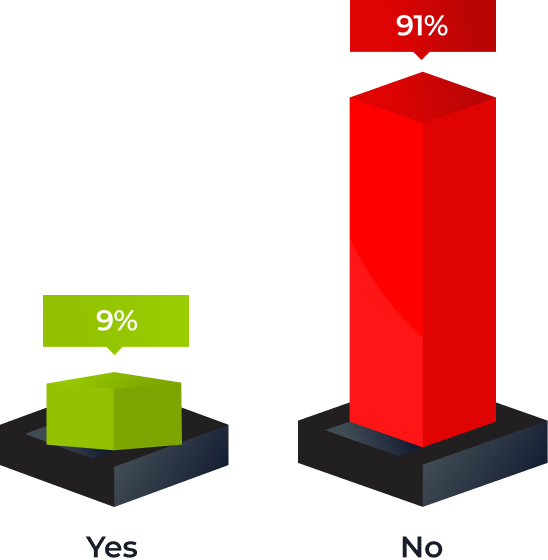
Have you ever used an all obe travel planning app?

In fact, a diagnostic survey among their customer base, including casual travelers, travel hobbyists, and digital nomads, revealed that 91% of users were juggling multiple apps to handle their trip needs, despite a strong demand for a convenient, all-in-one solution.

Therefore, they decided to strike while the iron is hot and upgrade their existing application for managing flights, accommodations, attractions, and other actions by replacing the in-app rule-based chatbot with Travel Ally, a frontline AI-powered travel assistant.

The enhanced solution was supposed to support users at every stage of their journey, with capabilities like:
Hassle-free booking

for accommodations, restaurants, museums, amusement parks, etc.

Real-time itinerary adjustments

to unexpected situations, such as lost documents, medical emergencies, and so on.

Trip researching and planning, all in-app

from choosing a destination and flight price tracking to checking weather conditions and selecting places to visit.

Collecting and analyzing post-trip feedback

to level up next travel experience.

Instinctools’ team worked side-by-side with the client’s in-house IT department, bringing in hands-on machine learning and generative AI expertise to help make their big bet on hyper-personalization and customer experience pay off.

Solution

Since the client was already using Amazon products, such as S3, Lambda, Athena, etc., it was agreed to build on this foundation, adding SageMaker and Bedrock.

  1. Deciding on the AI linchpin: multi-agent system (MAS)

A single AI agent couldn’t handle the range of tasks the client had in mind, therefore, our AI & ML team suggested a cooperative multi-agent system (MAS) where agents with different skill sets address different types of data and tasks.

The system was designed to process different types of data, as the specifics of the travel planning virtual assistant required agents to be well-versed in working with both unstructured data, such as customer reviews, and structured tabular data, such as financial data on flight and accommodation costs, etc.

Our technology stack included:

  • Amazon Bedrock with a wide selection of high-performing foundational models (FMs) to access advanced AI capabilities right away, without the hassle of data preparation, model building, or infrastructure management. We opted for the open-source Llama 2 as it excels in the precise detection of user intent.
  • Amazon SageMaker to customize, optimize, and deploy an FM model of our choice within a fully secure ML hub that seamlessly integrates with AWS Identity and Access Management (IAM) services for access control and governance.

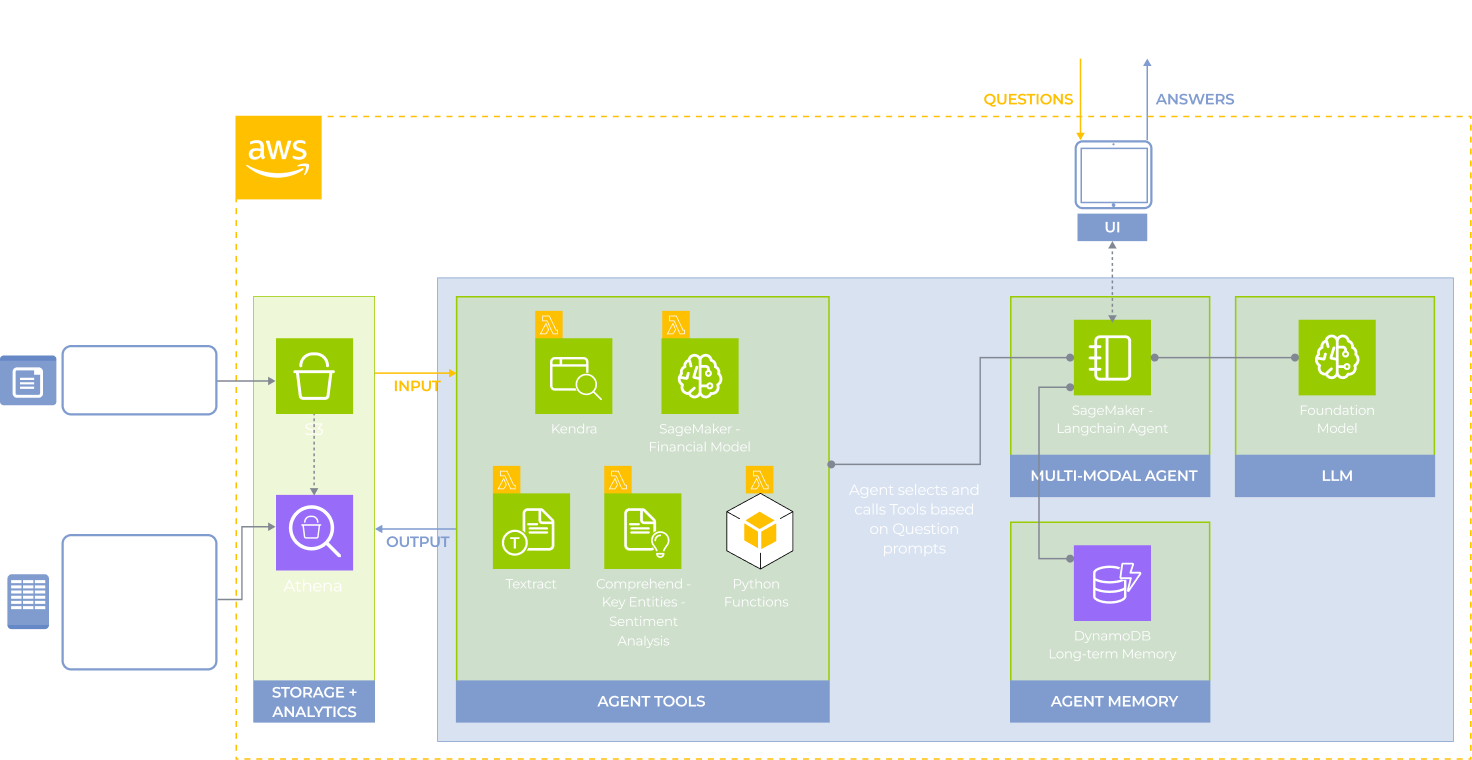
Here’s the high-level scheme of the solution’s architecture.

The virtual assistant follows a plan-and-execute flow: the planner maps out steps to answer the user’s query, while the executor activates the agent and tools needed for the task. For example, when processing structured financial data, the assistant relies on the LangChain framework. When dealing with unstructured information, such as reviews, the software invokes Amazon Kendra and the Python compute tool.

  1. Choosing the must-haves for the virtual assistant

Our intelligent travel assistant helps users create end-to-end travel plans that factor in:

  • Destination
  • Flight and accommodation cost
  • Vacation type (solo, family, business trip)
  • Activity preferences

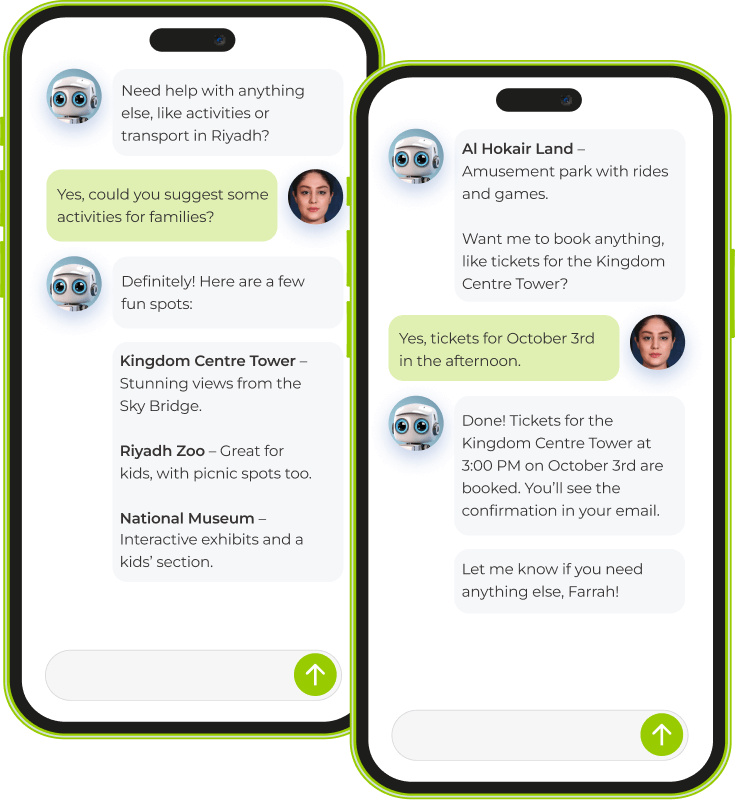
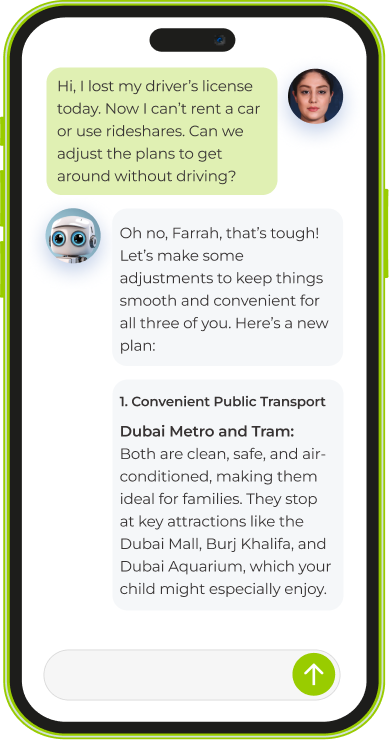
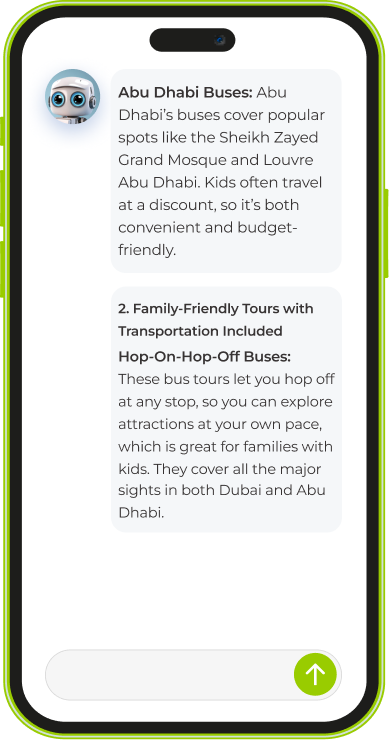
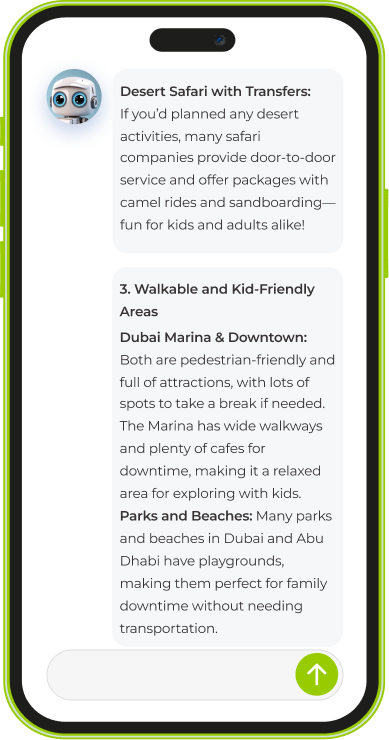
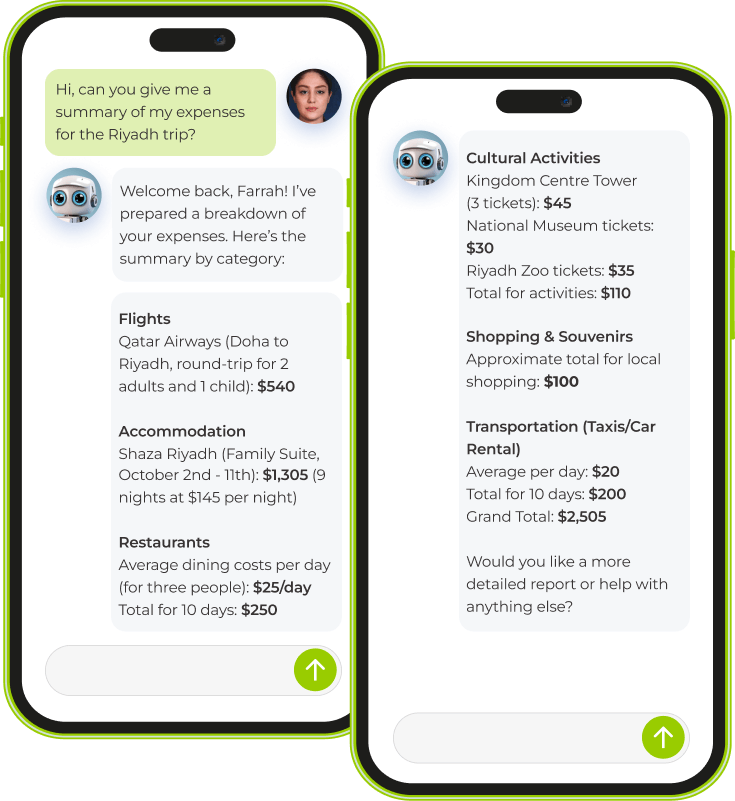
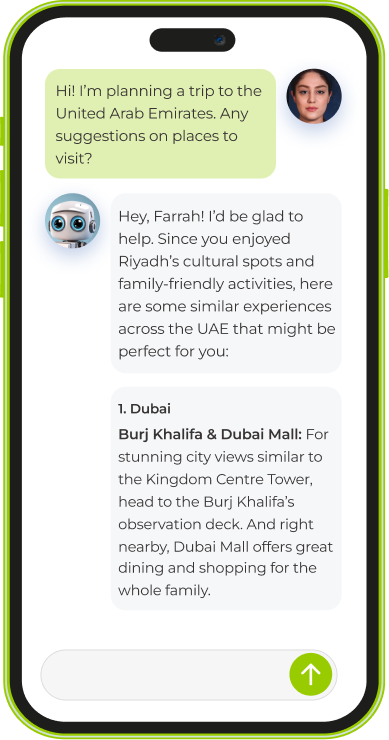
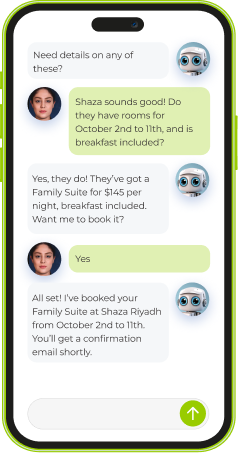
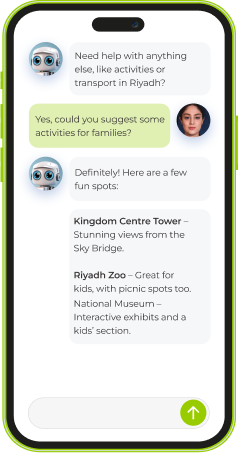
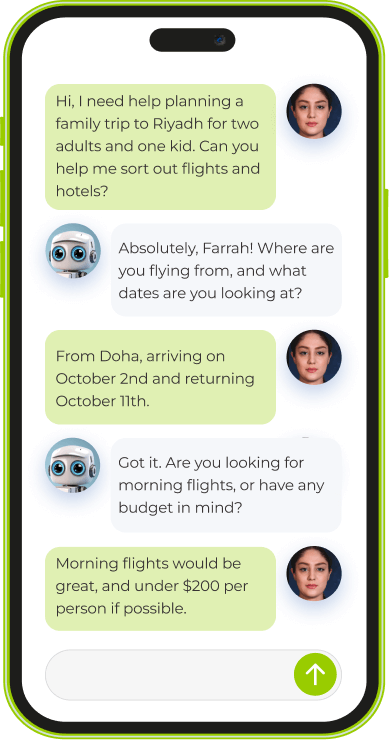
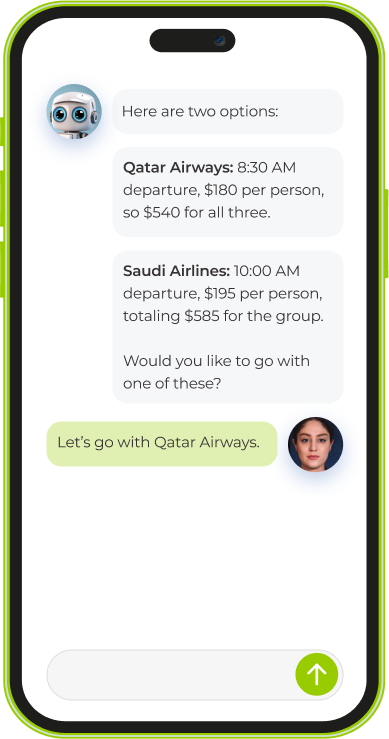
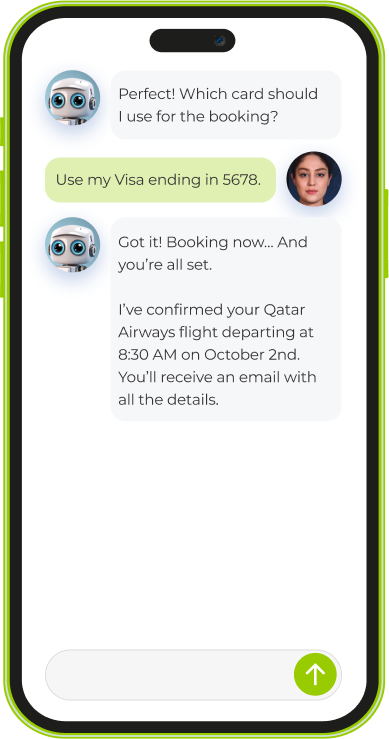
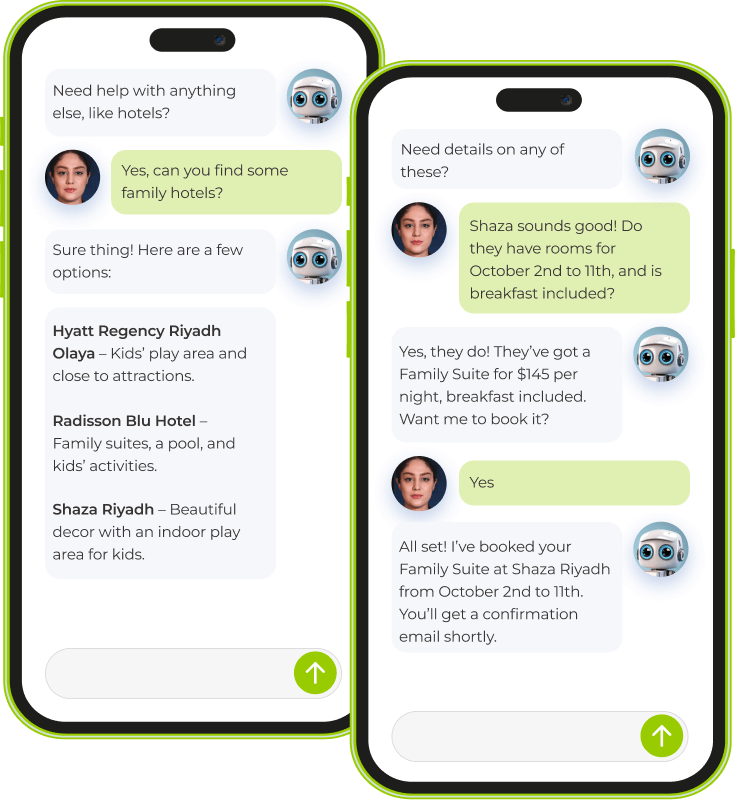
Below, there are a few examples of how Travel Ally handles conversations with a user planning a family trip across the Middle East.

Trip preparations tend to be overwhelming, with all the research and planning to ensure a comfortable journey. Travel Ally does its best to save users from getting bogged down in different airline and hotel offerings and filling in personal information manually.

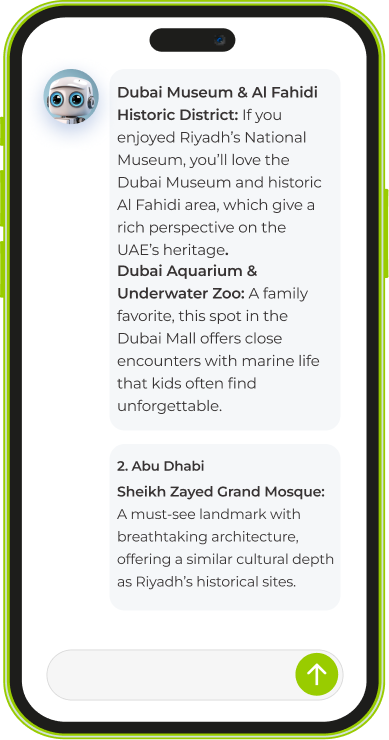
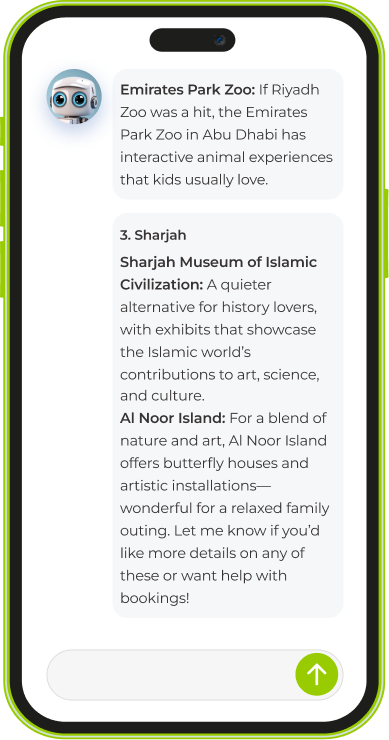
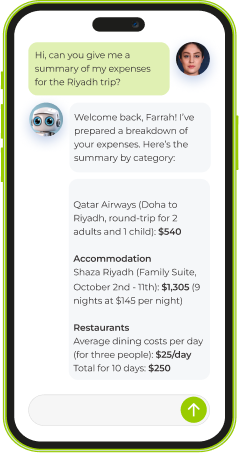
Here, Farrah gets the best-fit itinerary within minutes.

Do you have any specific requirements for accommodation options? Travel Ally got it covered.

Tailored recommendations on past-time activities are also just a query away.

If any emergency crops up during the trip, Travel Ally can rearrange your plans right away.

Tracking all travel-related expenses is also a walk in the park — providing a grand total is a part of post-travel experience and one of the top queries asked by all sub-categories of users. Travel Ally automatically counts every transaction executed by the underlying AI agents and also takes into account user queries made during the trip, such as “I went to a movie and paid for the ticket in cash, add these $15 to the expenses.”

The best bit of the AI-driven virtual assistant is that it remembers previous conversations. Therefore, the user’s next trip planning automatically relies on this data, providing personalized recommendations even when not asked for them directly in the prompt. For example, Travel Ally already remembers that Farrah travels mostly with a family and offers places to visit similar to the ones she approved for the prior journeys.

The planner was rolled out in March 2024, achieving results the client once thought were out of reach. For instance, last-minute cancellations decreased by 12%, the average transaction value stepped up by 15% thanks to wise cross- and upselling, and the annual retention rate spiked from 28% to 41%.

However, providing highly relevant, personalized responses would be impossible without optimizing the foundational model. See how we approached perfecting the assistant’s output.

  1. Optimizing the assistant’s output with retrieval-augmented generation

Even though pre-trained models like Llama 2 are capable of answering general queries, they still call for custom touch to fully adapt to a particular domain. Fine-tuning is one of the LLM optimization techniques that can be run for this purpose, but it relies on the knowledge learned during training on a static set of the client’s data. Meanwhile, the client wanted their system to give real-time responses based on the latest data.

To reach this, our AI development & ML experts have chosen retrieval-augmented generation (RAG), as this approach allows:

  • Keeping responses fresh, as a language model can be connected directly to any frequently updated data sources.
  • Bypassing retraining the entire model, since the LLM can access the new data in real-time.
  • Providing answers with source attribution, such as citations or references to sources, thus increasing the assistant’s credibility.

Nevertheless, at scale, single-agent RAG can be associated with a challenge of latency when reasoning over diverse information sources. Therefore, we addressed the issue head-on by setting up a multi-agent RAG flow.

It benefits the virtual assistant in two ways:

  • Asynchronous operation reduces latency by parallelizing retrieval, so slower operations don’t block faster ones.
  • Modular architecture enables easy horizontal scaling and adding new data sources, as well as more agents to cover a broader spectrum of tasks.

Before

After

Business value

  • The very first all-in-one AI-powered virtual assistant for seamless travel planning in the GCC region
  • 13% growth in the annual retention rate over a year
  • 15% increase in booking conversions, with users finding options that closely match their interests
  • 40% drop in the time required to complete a booking
  • 12% decrease in last-minute cancellations, as travelers feel more informed and supported
  • 15% boost in the average transaction value driven by users being presented with relevant add-ons

Client’s testimonial

Hear about the project directly from the CTO:

Multiplier effect

Travel and hospitality isn’t the only industry ripe for next-level customer experience with the help of generative and conversational AI. Anywhere customer service comes into play, companies can wring value from AI-driven chatbots and virtual assistants.

Given the rapid evolution of this tech, it’s not a question of nice-to-have anymore, but a requirement to follow if you want to meet the high expectations of today’s customers.

Conversational AI Chatbot For a Bank

Conversational AI Chatbot For a European Bank

How strengthening their existing chatbot for customer support with GPT-4 capabilities and voice assistance empowered a Czech bank to boost their 30-day retention rate by 7%, Net Promoter Score (NPS) by 34%, and First Contact Resolution (FCR) by 60%.

Industry:
Finance

Software Product Development

AI Development

Business challenge

The worldwide shift from brick-and-mortar banks with face-to-face interactions to online banking in the 1990s was a major disruption of the banking industry. Since then, it has been one of the technologies shaping the future of finance.

However, customer expectations have evolved over the decades. Customers of all generations shifted towards resolving their queries through a chatbot in a banking app rather than making a call, emailing, or visiting a physical location.

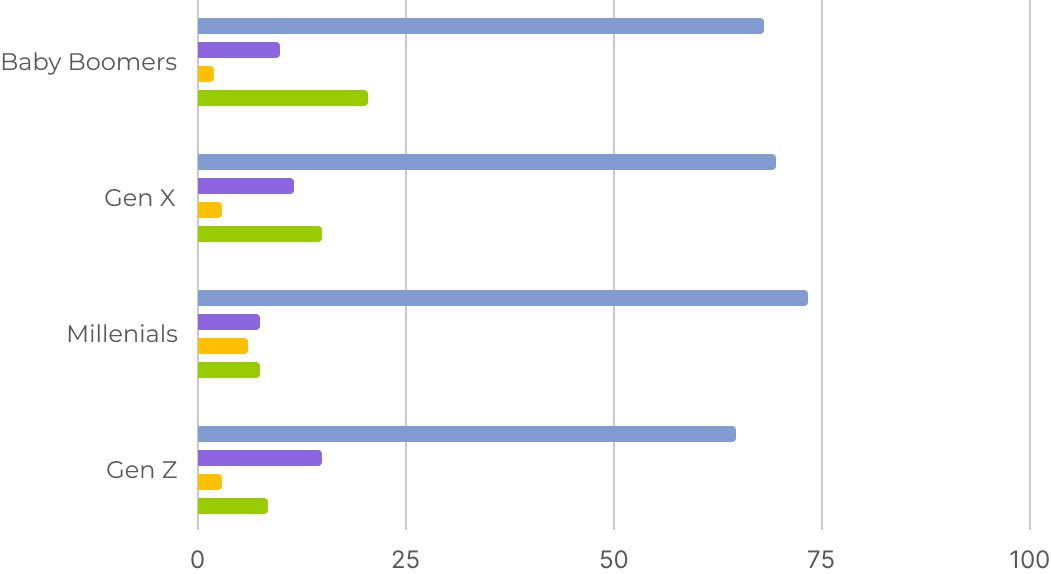
Most-used banking communication channels among different generations

Source: American Bankers Association, 2023

The gen AI boom became one of the main contributors to the rise of customer demands. End users were starving for more human-like, efficient, and fast communication in mobile banking, especially with chatbots as a leading communication channel. And banks had to shape up or ship out.

Our client – a trailblazing Czech bank – saw it as a golden opportunity and didn’t miss the chance to capitalize on it. They have been pushing the frontiers of local banking since 2015, and when the gen AI spike started, the client’s center of excellence immediately concentrated on quick-win strategies of implementing conversational AI in finance services. Enriching their existing chatbot functionality with natural language processing (NLP) and generative AI capabilities became one of the projects at the top of their priority list.

To undertake the initiative, the client needed an AI-savvy tech partner by their side to confidently and safely integrate the new tech. With data security being a high-stakes issue, they were looking for a vendor conformed to the ISO 27001:2022 standard. Instinctools’ data scientists and software engineers took the lead in crafting a stable and secure conversational AI chatbot.

Solution

The client envisioned a gen AI-powered chatbot with an intelligent Siri-like voice assistant. Such an ambitious solution required in-depth knowledge of large language models (LLMs), pattern and speech recognition, and other frontier technologies.

  1. Choosing the project’s AI linchpin

The client’s app has over 100,000 users, and they needed an LLM capable of handling a large volume of customer queries simultaneously. ChatGPT 4.0 was a go-to option, as it can process 12,000+ inquiries and transactions per second even in peak hours. Moreover, this pre-trained language model is well-versed in basic banking concepts and doesn’t require extensive fine-tuning, enabling swift project development.

However, finance institutions can’t hop on the open-source large language model right away due to restrictions of compliance regulations, such as GDPR, CCPA, etc. Banks had to use private models running in a controlled environment.

Hence, we deployed a private instance of GPT-4 within the client’s Azure tenant, connected their initial platform-based chatbot to the LLM through the API, and proceeded with rewiring the banking chatbot’s functionality.

  1. Stepping up text chatting patterns

Moving forward, we provided the LLM access to a sanitized dataset of internal banking data, such 
as answers to the FAQs, information about bank offerings, user guidelines for performing various operations, etc. As a result, human-like conversations have covered finance and card management, transactions, loan management, investing, savings account creation, credit score monitoring, filing insurance claims — the list can go on and on.

Here’s a high-level scheme of how GPT-powered banking chatbot works:

Integrating GPT-4 capabilities for customer support enabled the bank to solve user queries at least four minutes faster than with their previous middling chatbot. LLM implementation also helped decrease the number of requests that escalated to human support from 37% to 2% and step up First Contact Resolution (FCR) by 60%.

  1. Enabling full digital banking capabilities at the tip of a finger… and tongue

Motivated by their rapid gains, the client doubled down on reimagining user experience with conversational AI for finance. They announced pre-subscription to the new trailblazing features for their existing customers, who give explicit consent to access some of their profile data. In exchange, users were offered to be the first testers of a highly intelligent feature, a personalized virtual financial advisor. By analyzing customer data, their saving and expense patterns, the chatbot provides tailored insights, proactively helping users reach their financial goals.

Another grand step was the adoption of automatic speech recognition (ASR). Customers can now effortlessly manage their finances with simple, conversational commands. With voice-activated banking, users can send money, check balances, and more, all with the ease of a casual conversation. For example, if a user says, “Send €150 to my mom,” the bot will immediately generate a confirmation form for this request.

Pattern recognition under the hood of the chatbot enables it to anticipate the user’s needs, spotting keywords, such as “pay”, “send”, “transfer”, etc.

Here’s, for instance, how the software reacts to the word “send” based on the user’s spending habits.

Other examples of operations the voice assistant covers include managing users’ cards, monthly budgeting, creating savings accounts with goal setting, making investments, and much more, all directly from the dialog box.

Here’s an example of a conversation for reporting and blocking a lost card. The assistant guides a user through identifying the missing card and provides information for the next steps, including ordering a new card at the nearest branch.

An experimental AI-driven chatbot has been a resounding success with users, resulting in a 7% boost in a 30-day retention rate. After making this feature available for all the users, our client also saw a noticeable increase in customer loyalty and satisfaction, measured in Net Promoter Score (NPS), which went up by 34%.

Before

  • Old chatbot could cover only the most rudimentary user queries
  • 37% of queries escalated to human support
  • Text-based communication with the application

After

  • Advanced demand forecasting with a deep learning engine at its core
  • New chatbot can serve as a personal financial advisor
  • 2% of user queries get to the client’s call center
  • Interaction with the app through a voice assistant

Business value

  • The first gen AI-driven personal financial advisor in the Czech mobile banking market
  • 60% step-up in First Contact Resolution (FCR)
  • 75% increase in Query Deflection Rate
  • 7% boost in a 30-day retention rate
  • 34% rise in Net Promoter Score (NPS)

Multiplier effect

As much as conversational AI in finance is reshaping the banking sector, it’s also changing the game for other domains, from healthcare and ecommerce to manufacturing and logistics. If your app implies communicating with end users, it has room for gen AI adoption.

Conversational AI enables your app to intelligently process users’ needs on the fly. Just like saying “I’ve lost my card” initiates a card-blocking procedure, AI streamlines critical processes in other industries.

ML Demand Forecasting For an Ecommerce Company

ML-Powered Demand Forecasting For a Canadian Ecommerce Company

How replacing a traditional forecasting model in Excel with ML-based demand forecasting and Power BI visualization empowered a Canadian clothing retailer to step up their long-term forecasting accuracy from 23% to 92%, lower stockouts to 10%, and keep overstock within the 5% range.

Industry:
Ecommerce

Software Product Development

AI Development

Business challenge

Understanding exactly what, when, and in what quantities your customers want is a prerequisite to building a stable ecommerce business. Therefore, all ecommerce companies use some form of demand forecasting, often relying on rule-based linear regression analysis in Excel. However, as the ecommerce landscape continues to evolve, reaching the point when good enough isn’t enough anymore.

While traditional methods might still work for short-term planning, they keep failing to highlight longer-term insights. Quickly processing data from multiple external and internal sources or providing a comprehensive view of future trends is simply beyond the rigid systems’ capacity. The complexities of modern consumer behavior, influenced by myriads of fluctuating factors, require more advanced solutions — specifically, machine learning (ML) algorithms. For instance, present-day ML-based demand forecasting models are known to provide up to 98% accurate predictions.

Our client — a Canadian clothing manufacturer and online retailer — wanted to go beyond Excel-based analytics and myopic demand forecasting, solely grounded on historical dynamics and static consumer buying patterns. With garment factories in Vietnam and a customer base in Canada, they expected an intelligent forecasting model to optimize inventory planning and supply chain management.

The major shortcomings of their current spreadsheets-based prediction model included:

  • Manual data analysis
  • High dependence on the analysts for data interpretation
  • Low accuracy of long-term predictions
  • ‘Bullwhip effect’ of supply chain inefficiencies
  • Inability to adjust forecasts to new data and market changes right away
  • Permanent stockouts and overstock

As the limitations of their current approach became more apparent, the client decided to explore ML-driven solutions and started scanning the IT market for a tech partner to craft a highly accurate demand forecasting model. They also wanted to combine ML forecasting implementation with the adoption of data visualization software to make demand forecasts easy to grasp for a wide range of users.

After evaluating several potential ISO-certified vendors, they delegated the project’s heavy lifting to *instinctools’ dedicated team of top-tier data analytics experts, ML engineers, and BI specialists.

The outcomes they expected to achieve within our cooperation included:

Long-term predictions

with over 90% accuracy

Automation

of the forecasting processes

Stockouts

< 10%

Overstock

< 5%

The capability

to instantly factor in new data and market changes

Multidimensional modeling

and comparisons of what-if scenarios for promotions, market fluctuations, etc.

Wide accessibility

of ML-powered insights thanks to integration with data visualization tool

See how we approached the task, what challenges we faced and overcame.

Solution

The client was already using Microsoft corporate products, such as Dynamics365, Azure SQL database, etc., so they wanted to keep their tech stack consistent and opt for Azure ML. Moreover, they were also leveraging Power BI for visual insights in other departments.

However, they lacked in-house capacity and expertise to manage this software implementation initiative. Therefore, the *instinctools team was tasked with developing and integrating demand forecasting and data visualization tools into the client’s software ecosystem.

Here’s a system overview.

  1. Training a recurrent neural network (RNN) on the client’s data

Azure ML allows you to train your own ML model, save it in the registry, and then deploy in production. Based on our hands-on experience in similar projects, we chose a recurrent neural network (RNN) as a go-to option for demand forecasting tasks. After getting the client’s approval, our data scientists and ML engineers proceeded to work on the model’s exact architecture to incorporate the client’s dataset.

As the client has been considering implementing an ML-powered demand forecasting model for a while, they’ve put data cleanliness, accuracy, and completeness on the front burner long before taking on the ML adoption. Nevertheless, our data scientists run data cleaning procedures to ensure the dataset with diverse information from the client’s website, social media, third-party marketplaces, etc. is neatly organized. It greatly contributed to fast-tracking the project and getting a precise forecasting model that accurately reflects customer behavior and preferences while taking into account macro- and microeconomic events.

We split the data into training and validation sets, following the standard 80/20 ratio — 80% of data for training, and the rest 20% for validation. Splitting was performed randomly to eliminate bias in both sets and, thus, boost the model’s prediction reliability.

As the client didn’t have the necessary high-performing GPUs in place and didn’t plan to update their hardware park in the near future, it was more budget-wise for them to leverage Azure-based computing resources for the RNN training rather than invest in their own GPUs.

Through multiple re-training cycles of the ML-powered prediction model, we hit the 92% accuracy mark, with potential to reach 98% over time.

  1. Addressing two major challenges of ML-driven demand forecasting

Ensuring a seamless ML lifecycle

The adoption of AI and ML isn’t all sunshine and rainbows. To preempt issues that might affect the model’s performance, we established a structured and transparent ML workflow, relying on best MLOps practices:

  • Automated data pipelines for data collection and preprocessing
  • Version control of the model training
  • Standardized and traceable deployments
  • Auto re-training mechanism in case of data changes
  • Continuous model performance monitoring with auto alerting of any issues

Tackling software maintenance complexity

You still need human oversight to make the most out of artificial intelligence. Since the client doesn’t have in-house data scientists and ML engineers, they decided to retain our experts for adaptive software maintenance to modify the model in line with the updates in the company’s policies, regulations such as GDPR, and other possible post-deployment changes. Our specialists also stay in charge of regular re-evaluation and updates of the training and validation sets.

  1. Making ML-based demand insights accessible across the company

Accurate demand forecasting means nothing if not followed with timely actions. However, outputs generated by ML models are primarily designed for data scientists, limiting their accessibility to other employees. To democratize ML tools across various departments, the client decided to use Power BI for data visualization.

Both Azure ML and Power BI being part of the Microsoft stack allowed for seamless integration, enabling automatic updates to visualizations whenever the prediction model is re-trained.

Here’re the examples of analytical dashboards the client was provided with.

Before

  • Excel-based demand forecasting limited to linear regression analysis
  • Failure to take into account all valuable external and internal data
  • High reliance on manual processes
  • Poor accuracy in long-term forecasts
  • Permanent stockouts and overstock

After

  • Advanced demand forecasting with a deep learning engine at its core
  • Holistic ML model incorporating multiple internal and external data sources
  • Automated data processing and forecasting
  • High-fidelity long-term demand forecasts
  • Mitigated shortages and overstock

Business value

  • 92% demand forecasting accuracy
  • Stockouts reduced to 10%
  • Overstocks below 5%

Multiplier effect

Is there an industry where you can hit it big without meticulous planning backed by accurate demand forecasts? Be it ecommerce, healthcare, manufacturing, entertainment and media, or any other sector, as a business owner, you have to constantly balance your offering against customer needs and market changes. Switching from spreadsheets to frontier forecasting can improve operational efficiency by a mile in predicting hospital visits and the need for medications, anticipating power consumption, or planning workforce — the list can go on and on.

CANet healthcare platform

E-Health Product —
a Revolution for Canadian Cardiac Care

How crafting a virtual healthcare platform for clinics, research centers, and patients empowered a pan-Canadian healthcare association to rewire research and monitoring of high-risk cardiac patients with ICDs (implantable cardiac defibrillators), run 78% of check-ups remotely, and reduce the number of cardiac-related emergency hospitalizations by 21%.

Industry:
Healthcare

Software Product Development

Mobile App Development

Web Development

Business challenge

Establishing robust, consistent communication has its sway in any industry. However, in healthcare, this becomes a life-and-death matter. The regular collection of patient data enhances scientific knowledge about diseases, and constant health status monitoring of high-risk patients can literally save their lives.

Nevertheless, even though patients, clinics, and research labs are parts of the healthcare ecosystem, they are still very siloed, and so is their data. Moreover, healthcare institutions can’t keep up with the growth of medical-related data, often failing to process it effectively to get the valuable insights needed for treatment and research.

Under-digitalization and under-communication within the Canadian healthcare system were in the spotlight of our client – the Cardiac Arrhythmia Network of Canada (CANet). The association wanted to address the hurdles faced by various parties within the healthcare ecosystem.

Patients:
  • Aren’t in control of their personal health data
  • Need a budget-friendly remote alternative to costly and time-consuming post-surgery follow-ups at the clinic
  • Don’t have a credible and easy-to-access source of up-to-date information related to their diseases
Clinics:
  • Lack of systematization in electronic record-sharing when collecting patient data from other healthcare facilities
  • Unable to keep up with the current workload without remote monitoring and a specialized digital solution for it
Research centers:
  • Don’t have access to a regular source of relevant data
  • Waste employees’ time processing heterogeneous data to find valuable information

Our client intended to rewire the state of the Canadian healthcare system and decided to test the waters with a product for a specific patient group, clinics, and research centers (RC). It was planned that the project would have these elements:

  • Android and iOS apps for the patients
  • Web apps for healthcare providers and research centers

After evaluating several potential tech partners, CANet opted for *instinctools because of our proven expertise, European-based location, and readiness to set up a 13-person project team in less than three days.

Client’s goals

Facilitate communication between the patients, clinics, and research centers within a cohesive healthcare platform.

“We wanted to create a constant feedback loop between the patients, clinics, and research centers.”

Dr. Anthony Tang, CEO and Scientific Director, CANet

“Our platform – VIRTUES® – utilizes state-of-the-art diagnostics with advanced analytics and wireless connectivity to provide cardiac patients access to affordable on-demand virtual care.”

Dr. Anthony Tang, CEO and Scientific Director, CANet

Create a trailblazing patient-centered healthcare solution in Canada.

Reduce the number of non-mandatory visits to the clinics by up to 80%.

Minimize hospitalizations and emergency department visits by up to 20%.

“Another milestone we’ve set for VIRTUES® was reducing cardiac-related workload on clinics.”

Dimitri Popolov, Research Data & Systems Manager, CANet

Solution

As time-to-market was critical for the client, we suggested banking on cross-platform options. Flutter and React Native were top choices, but as CANet also needed web apps, our team decided to leverage React Native for mobile apps and React JS development for web apps.

This combo yielded triple wins:

  • Budget-friendly cost

As React Native is a React JS-based framework, the client didn’t need two separate teams to create mobile and web applications.

  • Fast-track development

Core React concepts are the same, which empowers the dedicated team to move through the whole process faster.

  • Simplified maintenance of all solutions

Relying on programming languages of the same type, with similar development approaches and code styles, makes software support a walk in the park.

  1. The tech groundwork
    of the platform

Before getting into the look and feel of the applications, we had to check all the boxes regarding regulatory compliance to ensure a smooth launch for VIRTUES®.

Every healthcare-related software product targeted at the Canadian market has to comply with the Personal Health Information Protection Act (PHIPA) and Privacy Impact Assessment (PIA) regulations.

Moreover, CANet wanted to take into account the HL7® FHIR® (Fast Healthcare Interoperability Resources) standard that has become a global best practice for a fast and secure health data exchange between healthcare applications.

These compliance goals required the selection of a relevant tech stack for the VIRTUES® data architecture. As all the components had to be FHIR-compliant by design, CANet ended with this set of software solutions:

  • SMART on FHIR as a healthcare-oriented platform with a plethora of open-source tools for crafting robust and secure clinical and patient-facing apps. It helps easily integrate apps with electronic health records (EHRs) and other healthcare software and standardizes data access.
  • Smile Clinical Data Repository (CDR) as a data repository for managing and maintaining the HAPI-FHIR Library that enables faster development cycles and allows the running of multiple clinical and research studies.

The system has an in-built OAuth2/OpenID Connect server, providing the client with the possibility to hone PHI safety while leveraging ready-made SMART applications instead of building their own solutions from scratch.  

  • Research Electronic Data Capture (REDCap) with the module Clinical Data Interoperability Services (CDIS) as a tool for collecting data from EHRs. It’s a standard for healthcare research programs that ensures top-level security of databases with Protected Health Information (PHI).

CDIS module supports batch data pulls from the EHRs and internal CANet clinical studies, providing research centers with data processing speed that was beyond the reach before.

Instinctools’ team was in charge of VIRTUES® integration with REDCap and Smile on the clients’ way to building an all-encompassing healthcare ecosystem with adequate engagement of all the parties:

  1. Mobile applications for patients’ monitoring

VIRTUES® is targeted at patients with an increased risk of sudden cardiac death (SCD). All the patients have cardiac implantable electronic devices (CIED) that require constant performance monitoring.

However, regular check-ups at the clinic are time-consuming and costly. Offering patients a solid healthcare digital solution for remote self-monitoring could have ensured high-level, affordable healthcare services for Canadians. This idea became the foundation for the patient-targeted iOS and Android apps developed by our dedicated team.

Implantable cardioverter defibrillator (ICD) performance monitoring

Aside from having Medrtonic’s cardioverter defibrillators implanted in their body, patients are given a specialized device reader to capture the data ICD produces. Then, the Bluetooth-powered reader transfers data to the mobile and web apps.

To ensure patients were able to take agency over their own healthcare when communicating with their physician, we designed mobile app reports in an easy-to-understand way. They contain:

  • Basic ICD information, such as current battery life, pacing and shock settings
  • Timesheet of recorded shocks, if any where delivered to a patient

As all the trial patients belong to a high-risk group, we added a notification function, enabling the patient to contact the clinic immediately, especially if there are any issues with a person’s ICD status. As the clinic receives the same report automatically, they are also able to get in touch with the patient without delay.

Our business analyst also suggested adding the category “Medications” to a section with medical information, so that users always have their current prescriptions on hand.

Library with expert-directed materials about cardiac diseases

Additional patients’ pain point VIRTUES® addresses is a lack of a credible and easy-to-access source of up-to-date information related to cardiac diseases. The mobile app has a library of educational materials in various formats — images, videos, PDFs — all verified by unbiased CANet experts.

  1. Web app for clinics

According to CANet, there are over 97,000 cardiac patients across Canada. Daily tracking of each individual’s overall health status and ensuring their implants work hassle-free was beyond the reach, given the 1,000+ emergency departments in Canada. Therefore, they needed a digital health solution to ensure adequate care for all the patients.

VIRTUES® web app aimed to cover this gap. The pilot trial involved 1,400 patients across 15 clinical sites throughout Canada.

As mentioned earlier, healthcare providers automatically receive reports about the patient’s ICD status. They include:

  • Patient’s personal data, such as name and date of birth
  • ICD data, such as its type and model, battery longevity, and patient-specific settings

Unlike summaries in patient-facing mobile apps, these reports are more detailed and contain cardiograms recorded by the reading device. Here are several examples:

Moreover, this data is coupled with the patient’s health information from the EMRs, allowing for a broader picture of the individual’s current health condition and enabling doctors to spot the problem areas faster.

On-field tests proved this digital solution is highly scalable. Before VIRTUES®, clinicians spent at least 45 minutes per patient for a standard intracardiac electrogram (EGM). Given the high number of patients, cardiologists across the 15 trial clinics had a 57-hour workweek on average.

With the VIRTUES® web app, they don’t have to invest their time in the EGM procedure, as data is recorded remotely and automatically. All the doctors need to do is interpret the EGM results and contact the patient in case of abnormal patterns. The digital platform made it possible to relieve healthcare professionals of excessive workload.

Now, one cardiologist can easily manage 25+ remote patients daily without compromising the healthcare quality, while earlier, the maximum per doctor was seven high-risk individuals.

  1. Web application for research centers

As the ongoing research of cardiac diseases helps to hone overall healthcare, CANet invested efforts into developing a solution for the research centers (RC) within the VIRTUES® platform.

Instinctools’ team created a web application that receives the data from the patients’ app and EMRs’ records and transforms this information into reports for research purposes.

RCs get de-identified files, where patients only have study IDs. Here’s an example of an anonymized report header:

Cardiovascular reports include:

  • Patient’s date of birth and study ID.
  • Individual’s type of heart disease, CABG, NYHA class, etc.
  • Information about their current cardiac medication, recent cardiovascular investigations, and hospitalizations.

Paired with data from the other studies conducted by the CANet association, this information has become the backbone of this leading-edge cardiac research in Canada.

Before

  • Patients, clinics, and research centers are separate entities of the healthcare system
  • Inability of the healthcare providers to ensure all the patients get timely and more accessible medical care
  • Patients with ICDs have to visit clinics for monthly check-ups
  • Scarcity of expert educational materials for patients
  • Сardiologists suffer from excessive workload
  • Lack of a constant source of relevant data about cardiac patients

After

  • Consistent communication between patients and healthcare providers
  • User-friendly platform for remote patient self-monitoring
  • Patients need to visit their healthcare provider only when unusual patterns are spotted instead of regular monthly check-ups
  • Scientifically credible educational materials about cardiac diseases at the patients’ fingertips
  • Precautionary approach to managing health status of high-risk cardiac patients
  • Decreased workload
  • Ever-flowing stream of research-valuable data to the RCs

Business value

  • Remote patient monitoring capabilities for the patients and healthcare providers
  • Decrease in the amount of cardiac-related emergency hospitalizations by 21% thanks to a precautionary approach to health management
  • The number of mandatory in-clinic visits reduced by 78%
  • Cardiologists’ working week has been shortened from 57 to 42 hours
  • Increase in the number of patients a cardiologist manages daily from 7 to 25+ thanks to remote monitoring

Client’s testimonial

Here’s how the company’s CTO evaluates the project outcomes:

Anna Vasilevskaya
AI modified real photo
Anna Vasilevskaya
Account Executive

Get in touch

Drop us a line about your project at
[email protected] or via the contact
form below, and we will contact you soon.